Anticipate: Threat Intelligence and Exposure at Machine Speed
This chapter describes B1 Anticipate, the blue team function that turns reports, feeds and knowledge of the estate into the hypotheses, detection requirements and patch priorities that direct the rest of the team's work, and the part of B2 Detect that it feeds. AI now reads the reports, extracts indicators and techniques, correlates them with the estate and drafts candidate hypotheses. The analyst's job moves from reading to deciding which of those hypotheses matter, and to proving that what the AI extracted is what the source said. The chapter follows the path from report to hypothesis, shows intelligence kept as code, combines the public exposure feeds with local asset context, sets out what AI does well and badly in this work, and ends with the two hazards specific to the function: sources that adversaries can write, and the duty to share.
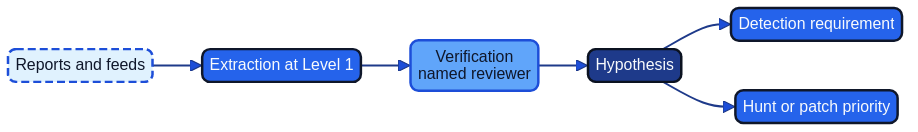
Figure 5.1: From report to hypothesis to detection requirement, with the human decision points and the verification step marked.
The chapter builds on conclusions of the earlier volumes. Architecture as Code (Chapter 9C) put threat handling in the codebase: intelligence arrives as STIX and TAXII through pipelines, and findings return as pull requests (61, Nordqvist, 2025). AI Platform and Security, Chapter 18, named patch velocity as a measured service level and detection at machine speed as commitments against AI-enabled adversaries (63, Nordqvist, 2026), and AI Governance, Chapter 24, concluded that patch decisions must be delegated in advance, because a weekly change advisory board cannot sit in the path of a known-exploited vulnerability (62, Nordqvist, 2026). AI Red Team, Chapters 10 and 13, supplied two rules this chapter applies to intelligence: AI proposes at Level 1 Assisted while a named reviewer decides each candidate against its provenance, and everything security AI reads may have been written by the adversary (64, Nordqvist, 2026). The question left open there, how an analyst verifies what an AI concludes when the evidence may be adversary-written and the analyst depends on the AI to read it, is taken up here for intelligence and carried into Chapters 8 and 14.
From report to hypothesis
A report is a claim about the world made by someone else, at a time, for their own purpose. B1 Anticipate converts such claims into three kinds of output the team can act on: a hypothesis (a statement about adversary behaviour that could be true in this estate and can be tested), a detection requirement (a specification for the detection engineers of Chapter 6) and a patch or mitigation priority (a ranking for the owners of the affected systems). A hunt, the subject of Chapter 9, is how a hypothesis is tested when no detection exists yet.
Before AI, the path was manual and narrow. An intelligence analyst, or in a small team whoever had the time, read advisories and vendor reports, kept a spreadsheet of indicators, and passed a handful of items to the people who tuned the SIEM. Most reporting was never read. What reached the estate was whatever the analyst had time for.
AI changes the throughput of the first steps and leaves the last step where it was. The pipeline in Figure 5.1 has five stages:
- Collection. Reports, advisories, feeds and open-source material arrive, as documents or as STIX objects.
- Extraction. An AI system running at Level 1 Assisted reads each item and proposes structured content: the techniques described, as MITRE ATT&CK identifiers (9, MITRE, n.d.), the indicators, the affected software and the targeted sectors. It also quotes the passage that supports each proposal.
- Verification. A named reviewer checks the proposal against the source. Nothing proceeds unverified.
- Hypothesis. For the verified items, the same assistant drafts candidate hypotheses by correlating them with what the team knows of the estate: which assets run the affected software, which telemetry exists, which techniques already have a detection. The analyst decides which candidates are worth the team's time.
- Routing. An accepted hypothesis becomes a detection requirement, a hunt, a patch priority, or a recorded decision to do nothing, with the reason.
There are two human decision points and one verification step. The decision to accept a hypothesis matters most, because it spends scarce engineering and hunting time, and it is the decision least suited to automation: the value of a hypothesis depends on the organisation's assets, the adversaries that care about it and the work already queued, none of which the report contains. The machine should widen what is read; the person should still choose what is acted on.
This is Shift 4 of The Transformed Security Architect applied to a team. The analyst conducts the extraction rather than performing it, and remains answerable for what is accepted (66, Nordqvist, 2026).
What the intelligence analyst does now
The analyst's work has four parts. Setting requirements means deciding which questions the function exists to answer for this organisation, such as which adversary behaviours target insurers with claims platforms or regional authorities with benefits systems; without requirements, extraction produces volume rather than direction. Reviewing extraction is covered below under verification. Judging relevance combines the verified content with asset knowledge. Closing the loop means telling the source community what was seen and learning, from the detections and hunts that came of the work, whether the function is producing anything. A function that cannot show a rate of conversion from intelligence to action is reading for its own sake.
Intelligence as code
Architecture as Code (Chapter 9C) argued that threat handling belongs in the codebase (61, Nordqvist, 2025). For B1 this means three things.
First, machine-readable exchange formats. STIX 2.1 defines objects for indicators, attack patterns, threat actors, campaigns and the relationships between them, and TAXII 2.1 defines an application-layer protocol for exchanging such objects over HTTPS through collections hosted under API roots (22, OASIS Cyber Threat Intelligence (CTI) TC, 2021). A pipeline that subscribes to a TAXII collection receives structured objects without a person copying text from a PDF. AI extraction then handles what is not yet structured: the long tail of advisories and vendor reports that exist only as prose. The pipeline's output should be the same STIX objects, so that extracted and received intelligence share one store and one set of checks.
Second, ATT&CK mappings as the common key. A technique identifier joins an intelligence item to a detection record, a hunt record and a coverage map. Without it, three teams describe the same behaviour in three vocabularies. With it, the question "which techniques in this month's reporting have no detection?" becomes a query.
Third, intelligence records under version control. Each item the team acts on becomes a record with its source, its extraction, the reviewer, the verdict and the links to what it produced. The record is the unit of audit: a supervisor, an auditor or a successor can see why a detection exists. It is also the unit of correction. When a source retracts a claim or a mapping proves wrong, the change is a reviewed commit, and everything downstream that cites the record can be found.
The records follow the conventions of the book's other artefacts. An intelligence record has the identifier form INTEL-HM-NNNN, a hunt record HNT-HM-NNNN and a detection record DET-HM-NNNN. Chapter 6 defines the detection record in full, and Chapter 9 the hunt record.
Worked example: from intelligence record to hunt and detection requirement (illustrative)
At Hansa Mutual, the three-person intelligence cell receives a report through the insurance sector's information-sharing arrangement describing credential theft against service accounts used by claims-export systems. The drafting assistant HM-SEC-002 (a Mode 5 identity held at Level 1 Assisted; AIDR-0312) extracts the technique and the described conditions. A cell member verifies the extraction, a hypothesis is accepted for the Polish service centre, where the claims-export service accounts (account group SVC-CLAIMS-EXPORT, 41 accounts) are most numerous, and the detection engineers receive a requirement. The record below is the artefact that stays in the repository.
# intel/records/INTEL-HM-0142.yaml  (illustrative)
id: INTEL-HM-0142
received: 2027-02-09
source:
  kind: sector-sharing-report
  reference: SHR-2027-014
  handling: restricted-to-group-soc
  reliability: reported-by-peer-organisation   # not independently confirmed
extraction:
  produced_by: HM-SEC-002
  autonomy_level: 1-assisted
  techniques:
    - id: T1078            # Valid Accounts
      quote_ref: "p3, para 2"
      grounded: true
  indicators:
    - type: ipv4-addr
      count: 14
      grounded: true
      expiry: 2027-03-09
  rejected_by_reviewer:
    - claim: "attributed to a named actor"
      reason: "source states similarity only; attribution not supported"
review:
  reviewer: intelligence-cell-member-2
  date: 2027-02-10
  grounding_check: all-proposals-traced-to-quoted-text
  seeded_error_in_batch: caught
verdict: accepted
hypothesis:
  id: HNT-HM-0031
  statement: >
    A stolen service-account credential is used from a host outside
    the service accounts' normal source set at the Polish service centre.
  account_group: SVC-CLAIMS-EXPORT     # 41 accounts
  decided_by: head-of-threat-intelligence
  decision_date: 2027-02-11
produces:
  - {type: hunt, id: HNT-HM-0031, opened: 2027-02-15}
  - {type: detection-requirement, id: DET-HM-0455, owner: detection-engineering}
review_by: 2027-05-11
decision_record: AIDR-0755
Three features of the record carry the chapter's argument. The reviewer rejected the attribution claim, which is the failure mode discussed below. Indicators carry an expiry, because an address that was hostile in February is often reassigned by April. And the hypothesis names the person who accepted it, so that the decision to spend the team's time is attributable.
The requirement DET-HM-0455 asks for a detection of service-account use from a host not seen before. Service accounts never answer multi-factor prompts, so the requirement leaves MFA signals out and rests on the source host and the account's normal behaviour. Chapter 6 follows it into a detection record.
Exposure at machine speed
Exposure awareness is the second half of B1. Intelligence says what adversaries do; exposure says what they could do to this organisation today. Three public feeds are the usual inputs:
- EPSS, the Exploit Prediction Scoring System, publishes for each published CVE a probability that it will be exploited in the wild in the next 30 days, refreshed daily (23, FIRST, n.d.).
- The CISA Known Exploited Vulnerabilities (KEV) catalogue lists vulnerabilities for which exploitation has been observed, and CISA advises organisations to use it as an input to their vulnerability prioritisation framework while assessing each asset's internet exposure (24, CISA, n.d.).
- The European Vulnerability Database (EUVD), launched by ENISA in May 2025 under the NIS 2 Directive, gives European organisations a source maintained within the Union's own cooperation structures (25, ENISA, 2025).
The three answer different questions. KEV says that exploitation has happened. EPSS estimates the likelihood that it will. EUVD adds European coverage and context. None of them knows anything about the organisation. A critical-severity flaw in software the organisation does not run is irrelevant, and a medium-severity flaw on an internet-facing system that holds claims data may be the most important item of the week.
The B1 task is therefore the join: each vulnerability from the feeds is combined with local asset context, which includes whether the asset is reachable from the internet, what data and business process it carries, whether compensating controls such as a web application firewall or segmentation exist, and whether a detection covers the technique used to exploit it. The result is a class, not a score. The Transformed Security Architect recorded the classes Hansa uses in its patch service level HM-PATCH-SLO-2027: exploited-exposed and exploited-internal, with mitigation within 24 hours and a fix within 72 (AIDR-0554) (66, Nordqvist, 2026). The classes are useful because the decision is made once, in advance, and the pipeline applies it.
Patch velocity as a measured service level
NIST's guidance on enterprise patch management describes patching as preventive maintenance to be planned rather than improvised (26, Souppaya & Scarfone, 2022). Two arguments from the earlier volumes make the planning concrete. The first is AI Governance, Chapter 24: a change advisory board that meets weekly cannot sit in the path of a known-exploited vulnerability, so the decision for a defined class is delegated in advance to named roles (62, Nordqvist, 2026). The second is the expectation, stated by the UK National Cyber Security Centre in May 2026, that AI used by skilled people can exploit long-standing technical debt at scale and force a wave of fixes, for which organisations should prioritise externally exposed systems, patch faster and more often, and adopt update-by-default (33, NCSC, 2026). The NCSC's wave is an expected outlook, attributed to the NCSC. That AI shortens the time from discovery to exploitation is stated as present fact by five national cyber agencies in June 2026, and is observable on their account (34, Five Eyes agencies, 2026). What is also observable is that the feeds above already exist and are used.
The blue team's contribution is the measurement and the join. Patch velocity belongs in management reporting as a risk indicator: for each class, the median and the 90th percentile of time from first appearance in a feed to mitigation, against the class's target. Hansa's board page for the fourth quarter of 2026 reported a median of 31 hours and a 90th percentile of 118 hours against a 72-hour target for exploited-exposed, which showed that the median was acceptable and the tail was not (66, Nordqvist, 2026). B1 owns the part of that figure that depends on knowing what is exposed and what is being exploited; the platform and application teams own the part that depends on fixing it.
The exposure prioritiser in each organisation is an AI-assisted component at Level 0 Advisory (NR-SEC-003 at Nordvik Region, HM-SEC-005 at Hansa Mutual). Level 0 is the right level for a ranking that feeds a delegated decision: the system ranks and explains, and the delegated roles act under the class rules. If a ranking ever drove automatic mitigation, that would be a delegation of a B4 action and would need a playbook manifest (Chapter 10), not a quiet change to a prioritiser.
What AI does well and badly
The evidence for the function is practical rather than statistical, and the chapter makes no claim about error rates because none are available for a given team's pipeline. The team's own measurement, described below, is the only number that matters. What can be said from the properties of the task is this.
AI does well at reading breadth (a system reads every advisory in the queue, in several languages, so that the constraint on coverage moves from reading time to review time), at structured extraction of techniques, products and indicators into STIX-shaped objects (where a quoted passage makes checking quick), at summarising one report for different readers, and at correlation with the estate: given an asset inventory and a telemetry catalogue, it can list which assets run the named software and which techniques lack a detection.
AI does badly:
- Hallucinated indicators. A system may produce an address, hash or domain that is not in the source, or alter one character of a real one. A single wrong indicator in a block list is an outage; a missing one is a gap.
- Wrong technique mapping. Mapping prose to ATT&CK is a judgement. A behaviour described loosely maps to a plausible but wrong technique, and the mapping then steers the detection engineer.
- Overconfident attribution. Reports use hedged language: "similar to", "consistent with", "may be linked". Summaries tend to flatten the hedge into a statement. Attribution rarely changes what a defender should detect and often changes how a board feels, so an unsupported attribution costs more than it appears to.
- Missing the staleness. An indicator's useful life is short and a report's date matters. An assistant that does not carry the date into the record produces intelligence that looks current after it is not.
- No knowledge of what the organisation has not told it. Relevance depends on assets and priorities. A hypothesis that is correct in general and irrelevant here consumes time.
These failure modes are why the extraction runs at Level 1 Assisted: the assistant proposes, a person decides, and the proposal arrives with the evidence needed to decide quickly.
Verifying extracted intelligence
The opening of this chapter left a question: how does an analyst verify a conclusion when the analyst depends on the AI to read the material? For intelligence the problem is milder than in triage, because the source document is a bounded text that a person can read. The design must still prevent the check from degenerating into approval. AI Red Team, Chapter 10, defined soundness for AI-proposed threats in advance and required a named reviewer to decide each candidate against its provenance (64, Nordqvist, 2026). The same structure applies, with five tests:
- Grounding. Every technique, indicator and claim in an extraction links to a quoted span of the source. A proposal without a span is rejected without further discussion. The pipeline checks mechanically that the quoted span exists in the document and contains the indicator verbatim, so that the human reviewer reads only items that have passed this check.
- Classification. The reviewer confirms that each technique mapping fits the described behaviour and that the reliability of the source is recorded as the source states it, not as the summary renders it.
- Sampling. In the first months, the reviewer checks every item. After the pipeline's error profile is known, the reviewer checks a defined share, and any item that would change a block list or a detection is always checked.
- Seeded errors. The team inserts known errors into a share of batches: an altered indicator, a mapping to a neighbouring technique, an attribution the source does not support. The catch rate is the measure of whether review is real, using the approach of The Transformed Security Architect, Chapter 14 (66, Nordqvist, 2026), and the oversight-quality metric introduced in AI Boss, Chapter 26 (67, Nordqvist, 2026). A falling catch rate triggers a return to full review; Chapter 14 sets the protocol for the whole SOC.
- A named reviewer who can disagree. The record carries the reviewer's name, the date and the verdict. The reviewer reads the source before reading the extraction where the item is high-stakes, so that the AI's answer does not frame the check.
Review quality is also measured at the level of the function: the share of extractions rejected or corrected, the time to review and the share of accepted hypotheses that were later found wrong. These measures are reported at team level. Where staff representatives have rights over measures that could be used to monitor individuals, they are agreed first (AI Boss, Chapter 23).
Hostile sources
Everything the intelligence pipeline reads is written by someone, and some of those writers are adversaries. The general defence, that the controls sit outside the model and that the reader holds no action tools, is set out for investigation in Chapter 8 and for the SOC's AI as a whole in Chapter 15; MITRE ATLAS lists the techniques against AI systems (10, MITRE, n.d.). For B1 the risk has three shapes, of which the first is the one Chapter 8 treats.
- Instructions in content. A report or feed entry may contain text that an extraction system treats as an instruction rather than as data.
- Poisoned content. An adversary who knows a team consumes a public feed may seed it with indicators for legitimate services, so that blocking them causes an outage, or with false reports designed to send analysts after the wrong thing. A less dramatic form is flooding: more plausible items than the team can review.
- Tampered provenance. A report that claims a trusted origin but does not have it. The grounding check does not catch this, because the quoted text is genuine.
The controls that are specific to intelligence do not depend on the model behaving well:
- The extraction system has no tools that act. At Level 1 Assisted it writes a proposed record to a queue and cannot update a block list, change a detection or send a message, so the worst outcome of a hostile document is a bad proposal that reaches a reviewer. A policy decision point outside the model moves a record from
proposedtoacceptedonly on a signed reviewer verdict. - Source trust is tiered and recorded. Government and CSIRT reporting, sector-sharing reports, commercial feeds and open-source material carry different reliabilities, and the tier appears in the record. Indicators from open sources do not reach a blocking control without corroboration.
- Indicators expire and blocking changes are reversible. An indicator in a block list has an expiry date and an owner, so that a poisoned entry ages out and can be rolled back.
The same logic limits what the drafting identity may do. The text an agent reads may have been written by the adversary, and an agent that could change production detections would give that writer a path to blind the SOC. No Mode 5 agent therefore changes detection content in production on the strength of what it reads; HM-SEC-002 holds a Mode 5 identity at Level 1 Assisted with write access to a branch and nothing else (Chapter 6).
The sharing duty
Intelligence work has a reciprocal side. The organisations that supply reports are other organisations' defenders, and what they publish was seen somewhere. NIS 2 treats cooperation and the exchange of cybersecurity information as part of the Union's framework and provides for the national CSIRTs, for the vulnerability database mentioned above and for arrangements for sharing information (3, European Union, 2022). The text of the Directive is the authority, and the exact obligations for an entity depend on its classification and on national transposition. For the blue team the architectural implication is that sharing is a designed outflow with decision rights, not an ad hoc act by a helpful analyst.
Three questions define the design:
- What may leave. Technical indicators and technique descriptions from the organisation's own incidents normally may; personal data, health data, claims details and customer identifiers may not, and the GDPR applies to log excerpts that contain them. Anything that reveals the organisation's own weaknesses, such as an unpatched system, needs the CISO's decision.
- Who may release. A named role, such as the head of threat intelligence, releases to external groups. An AI system drafts a sanitised version at Level 1 Assisted, and a person reads the whole of it before release, because sanitisation errors leak data.
- Under what handling. Received items carry the handling rules of their source, which the record stores and the pipeline enforces. A public authority has a further consideration: public-access rules may make documents requestable, so the record should state what is exempt and why.
Sharing also feeds incident reporting. The clocks of NIS 2 Article 23 are a requirement on the case record (Chapter 10); the intelligence function's share is the informal and structured exchange that precedes and follows a formal report (3, European Union, 2022).
Practical guide: Setting up a weekly intelligence-to-detection routine
Purpose. To make B1 produce a regular, measured flow of verified hypotheses into detection and hunting, with a named reviewer and a conversion rate, rather than an unread pile of reports.
Roles. The intelligence analyst (or, in a small team, the senior security analyst who holds the role), a reviewer who is a different person, a detection engineer, the SOC lead and, where it applies, the employee representatives for any measure that could be attributed to individuals.
Steps.
- Write three to five intelligence requirements that state the questions the routine answers for this organisation. Review them every six months and on a trigger such as a new system or a major incident.
- List the sources by tier and set the extraction pipeline to read only those. State each source's handling rules.
- Run the extraction at Level 1 Assisted with the grounding check on. The pipeline writes proposals to a queue, not to any control.
- Hold a 60-minute weekly review at a fixed time. The reviewer reads the proposals against the sources and records a verdict for each. Start with full review. Move to sampling only when the seeded-error catch rate has stayed at or above 0.80 for eight weeks, the threshold of the SOC review protocol in Chapter 14.
- Seed one error in every batch of twenty proposals (the 5 per cent of the SOC protocol), rotating between an altered indicator, an unsupported attribution and a neighbouring technique. Record whether the reviewer caught it.
- Decide the routing of each accepted item within the same meeting: detection requirement, hunt, patch priority or no action with a reason.
- Measure the conversion rate monthly: the share of accepted hypotheses that reached a deployed detection, a completed hunt or a changed priority within 30 days.
- Review the routine every quarter and at each change of pipeline, model or source tier.
# intel/routine.yaml  (illustrative defaults; adapt to the works agreement and risk appetite)
routine:
  cadence: weekly
  duration_minutes: 60
  extraction:
    autonomy_level: 1-assisted
    tools_that_act: []                 # extractor writes to a queue only
    grounding_check: required
  review:
    reviewer_differs_from_analyst: true
    seeded_errors_per_20: 1
    full_review_until_catch_rate: 0.80
    catch_rate_window_weeks: 8
    report_level: team                 # never by name
  routing_deadline: same-meeting
  conversion:
    window_days: 30
    target_share: 0.30
  expiry:
    indicator_default_days: 28
  next_review: 2027-07-01
Definition of done. Requirements and source tiers are in the repository; the routine has run for four consecutive weeks; every accepted item has a record with a reviewer and a routing; the seeded-error catch rate and the conversion rate appear in the monthly team report; the SOC lead has the next review date in the calendar. The thirty per cent conversion target is a starting default and should be changed once the team's own baseline is known.
Across the usage modes
The mode determines whose identity the AI uses and what it can do; the level determines who decides each action. For B1 the default ceiling is low, because the output of intelligence work is a proposal.
| Mode | Typical B1 use | Identity | Highest level this book recommends |
|---|---|---|---|
| Mode 0 Ambient AI | Enrichment and scoring inside a commercial intelligence or exposure product | The vendor's | Level 0 Advisory until its use and autonomy are established by contract |
| Mode 1 Conversational assistants | An analyst summarises a public report | The analyst's | Level 0 Advisory; no sensitive data |
| Mode 2 Embedded workplace assistants | Summaries and drafts inside mail and documents | The analyst's | Level 0 Advisory |
| Mode 3 Agentic work tools | An analyst's tool collects and compares sources | The analyst's | Level 1 Assisted |
| Mode 4 Built AI applications | The extraction pipeline and exposure prioritiser | The application's | Level 1 Assisted for extraction; Level 0 Advisory for prioritisation |
| Mode 5 Autonomous production agents | HM-SEC-002 holds a Mode 5 identity for extraction |
Its own | Level 1 Assisted; no Mode 5 agent changes production detection content |
The vendor row matters most in practice. Many commercial products already summarise, score or enrich on the buyer's behalf, which is the Mode 0 blind spot of AI Red Team, Chapters 8 and 28 (64, Nordqvist, 2026). The practical rule is to ask, before relying on a vendor's relevance score, what it uses, how it can be sampled and what happens when the model changes.
Outlook
- Observable. AI extraction of indicators, techniques and summaries from reports is used now, as are the exposure feeds described above. The risk of adversary-written content in the pipeline is documented in the ATLAS framework.
- Expected. The NCSC expects AI used by skilled people to force a wave of fixes and advises faster, more frequent patching (33, NCSC, 2026); that raises the weight of the delegated patch classes in this chapter. For the conversion of verified intelligence into deployed detections the book offers a design position and no forecast: it does not recommend conversion at Level 3 Bounded until the conditions of Chapter 6 hold.
- Speculation. Autonomous attribution by an AI system, without a person who can examine the evidence and answer for it, is speculation, and nothing in the present evidence supports treating it as reliable.
Nordvik Region and Hansa Mutual
The two organisations meet B1 from opposite positions, and the difference follows from the profile in the example-organisation document.
Nordvik Region has no intelligence analyst. It consumes the weekly reporting of the national CSIRT and the reporting of the regional-government information-sharing group, and it uses the exposure prioritiser NR-SEC-003 at Level 0 Advisory on its internet-facing services. The chapter's routine is adapted to a smaller scale. Karin Lund, the senior security analyst who becomes the Region's first detection owner (Chapter 26), holds the intelligence role for one weekly hour (AIDR-0705), so a 60-minute review meeting every fortnight is the realistic cadence, with a second analyst as reviewer. She also seeds the errors, and the second analyst reviews blind, as in the seeding practice recorded in AIDR-0715 (Chapter 14). The extraction runs on the Region's reserved capacity, because the pipeline's side-inputs include asset context that describes the Region's defences. Without a dedicated function, the conversion target is modest: a few hypotheses a quarter, tied to the rules the Region takes over from its provider (Chapter 6). Sharing is the Region's strongest B1 asset, since the sharing group gives a small team the experience of many peers, and its main constraint is that records of what is shared may be requestable under public-access rules.
Hansa Mutual has a three-person intelligence cell that uses the drafting assistant HM-SEC-002 at Level 1 Assisted and feeds the four detection engineers directly. The cell's work is the worked example above: records in the repository, a named reviewer, seeded errors, and a conversion rate reported to the SOC lead. Its exposure prioritiser is HM-SEC-005 at Level 0, and the delegated patch classes of HM-PATCH-SLO-2027 apply to what it ranks. The cell's decision to adopt the routine, with the rule that no Mode 5 agent changes production detection content, is recorded as AIDR-0755. Its risk is the reverse of Nordvik's: the volume of extraction can outrun the engineering capacity to use it, and a flood of accepted but unused hypotheses is as much a failure as an unread pile. Hansa's seven regimes also mean that a hypothesis relevant to the Swiss or UK entity may have to be shared under different rules, and the cell records the handling per entity.
The common point is that both organisations treat intelligence as a gate to action, with an owner, a reviewer and a measure, rather than as a reading list.
Summary
This chapter described B1 Anticipate and the demand it places on B2 Detect. AI now reads, extracts and correlates at a volume no analyst can match, and the function's value moves to the decisions that follow: which verified hypotheses deserve engineering and hunting time, which exposures are real in this estate and who may act on them without waiting for a meeting. The pipeline of Figure 5.1 keeps two human decision points and a verification step, because extraction can invent indicators, mislabel techniques and flatten the hedges of a source into an attribution.
Intelligence belongs in the repository. STIX and TAXII carry what arrives structured, ATT&CK identifiers join intelligence to detections and hunts, and a versioned record ties each accepted item to its source, its reviewer and its outcome. Exposure combines EPSS, KEV and EUVD with local asset context, and the resulting classes allow patch decisions to be delegated in advance. Patch velocity is reported as a service level, by median and by tail.
The sources of intelligence are not trusted, because adversaries write some of them. The extraction system therefore acts on nothing: it proposes at Level 1 Assisted, a policy point outside the model moves a record forward only on a reviewer's verdict, and no Mode 5 agent changes production detection content on the strength of what it reads. Review is made real by grounding checks, sampling and seeded errors, and by a catch rate that returns the team to full review when it falls. Sharing is a designed outflow with a named releaser and a rule about what may leave. Outlooks in this chapter are labelled: AI extraction and a shorter window from discovery to exploitation are observable, the NCSC's patch wave is expected, and autonomous attribution is speculation.
The next chapter turns to B2 Detect itself. Chapter 6 takes the detection requirement that this chapter produces and shows how a detection becomes a versioned record with logic, tests, an owner and a review date, with AI as a drafter whose work must pass the same test as anyone's.
Sources
- MITRE Corporation. MITRE ATT&CK: Adversarial Tactics, Techniques, and Common Knowledge. (9, MITRE, n.d.)
- MITRE Corporation. MITRE ATLAS: Adversarial Threat Landscape for Artificial-Intelligence Systems. (10, MITRE, n.d.)
- OASIS Cyber Threat Intelligence (CTI) TC. STIX Version 2.1 and TAXII Version 2.1. (22, OASIS Cyber Threat Intelligence (CTI) TC, 2021)
- Forum of Incident Response and Security Teams. Exploit Prediction Scoring System (EPSS). (23, FIRST, n.d.)
- Cybersecurity and Infrastructure Security Agency. Known Exploited Vulnerabilities Catalog. (24, CISA, n.d.)
- European Union Agency for Cybersecurity (2025). European Vulnerability Database (EUVD). (25, ENISA, 2025)
- Souppaya, M. & Scarfone, K. (2022). Guide to Enterprise Patch Management Planning: Preventive Maintenance for Technology. (26, Souppaya & Scarfone, 2022)
- European Parliament and Council of the European Union. Directive (EU) 2022/2555 on measures for a high common level of cybersecurity across the Union (NIS 2 Directive). (3, European Union, 2022)
- National Cyber Security Centre (2026). Preparing for a 'vulnerability patch wave'. (33, NCSC, 2026)
- Five Eyes cyber security agencies (2026). The AI shift in cyber risk: why leaders must act now. (34, Five Eyes agencies, 2026)
- Nordqvist, G. (2025). Architecture as Code. (61, Nordqvist, 2025)
- Nordqvist, G. (2026). AI Governance: Governing Artificial Intelligence in European Enterprises and Public Authorities. (62, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Platform and Security: Building and Securing AI Platforms in European Enterprises and Public Authorities. (63, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Red Team: AI as an Active Part of Cyber Defence in European Enterprises and Public Authorities. (64, Nordqvist, 2026)
- Nordqvist, G. (2026). The Transformed Security Architect: Role, Craft and Career in the Age of AI in European Enterprises and Public Authorities. (66, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Boss: When Artificial Intelligence Manages People in European Enterprises and Public Authorities. (67, Nordqvist, 2026)