Learn: Post-Incident Review, Purple Teaming and Detection Debt
This chapter describes B5 Learn as the blue team now has to run it: the post-incident review, the purple loop and the upkeep of detections, playbooks and mandates, in a team where AI drafts reviews, proposes improvements and tracks closure. It concerns B5 Learn above all, and it touches B2 Detect and B4 Respond because those are the functions whose artefacts a review changes. The chapter argues that a review is engineering, not ceremony: it ends in changes to code, and a finding is closed only when a re-test passes. It also names the risk that is new with AI, a review that reads well, is produced in minutes and teaches the team nothing.
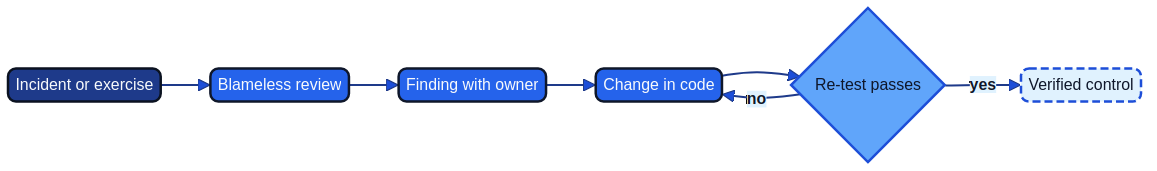
Figure 11.1: The learning loop from incident or exercise through finding, change, re-test and verified control.
The chapter builds on the finding-to-verified-control path of AI Red Team, Chapter 26, and on the conclusion recorded there: every finding, whether from an exercise, an AI red-teaming campaign, a chaos experiment or an incident, ends as a verified control, and a finding is closed only when the re-test passes (64, Nordqvist, 2026). It also takes over the classification of controls in AI Threat, Chapter 30: a control is a defence only when a test that re-runs its scenario has passed recently, and controls are classified verified, declared or failed (65, Nordqvist, 2026). Chapter 10 defined the playbook manifest and the stop path that this chapter tests, and Chapter 6 defined the detection record that this chapter maintains.
Review as engineering
A post-incident review is worth the time when it changes something that can be tested. The test is simple: after the meeting, is there a pull request, a contract change request or a mandate change with an owner and a date, and is there a re-test that will show whether the change works? If the answer is a document of observations, the review was a ritual.
The discipline has three parts. The first is that the review is blameless in the working sense of the term: it asks what made the actions of people and systems reasonable at the time, and it treats the conditions as the object of change. A review that ends with a name has found a person to blame and left the conditions in place, so the same conditions will produce the same event with a different name attached. The second part is that the review is evidence-based: every statement in the timeline points to a log line, a case record entry, an agent action record or an approval, and a statement without a pointer is marked as recollection. The third is that the review ends in code: the findings are changed detections, changed playbooks, changed mandate manifests, changed tender annexes or new tests, and each is a versioned artefact in the repository where the team already works. Architecture as Code (Chapter 27) puts the same habit as an Architecture Decision Record for an AI-assisted decision, written retrospectively if necessary (61, Nordqvist, 2025); a review record applies it to incidents.
The frameworks agree on where this sits. NIST CSF 2.0 includes an Improvement category (ID.IM) under the Identify Function, so that improvement is a continuing activity fed by incidents, tests and exercises, not a phase after the incident (17, NIST, 2024). The NIST incident-response profile places incident response in the same CSF 2.0 frame (19, NIST, 2025). The practical point for the blue team is that learning has an owner, a cadence and a backlog, as any other function has.
Practical guide: Running a blameless review in 90 minutes
Purpose. Produce three committed changes and a read-back that the people involved accept as an honest account, within 90 minutes and within 30 days of the incident.
Roles. A facilitator who was not the incident commander; a scribe; the incident commander; the analysts and, where one acted, the agent operator; the detection engineer who owns the detections involved; the owner of any playbook that ran; and, where the local agreement provides for it, an employee representative as observer. The SOC lead attends and does not chair.
Before the meeting. The scribe assembles the evidence pack no later than 24 hours before: the case record, the timeline generated from logs, the versions of the detection records and playbook manifests in force, the agent action log, the approvals and the stop-path timings. Pre-reading is mandatory, and nobody is asked to recall what the pack already shows.
Steps.
- Minutes 0 to 10: the facilitator states the ground rules (no names as causes, no performance assessment of individuals, nothing recorded that the works agreement forbids) and reads out the facts of the incident from the pack.
- Minutes 10 to 35: walk the timeline once. Each participant corrects entries against the evidence. Every correction is recorded, because the corrections show where the generated or assembled timeline was wrong.
- Minutes 35 to 60: for each decision point, ask what the person or system knew, what the tooling showed and what made the action reasonable. List contributing conditions, not causes.
- Minutes 60 to 80: choose at most three changes. Each has an owner who is a role, a due date, the artefact it changes and the re-test that will show it works. Defaults: 30 days for a detection or playbook change, 90 days for a change that needs a contract amendment or a procurement step. Adapt them to the contract and to the team's capacity, and write the adapted value down.
- Minutes 80 to 90: read back the three changes and what the team decided not to do and why. The scribe opens the findings in the register the same day.
Definition of done. The review record exists in the repository, every finding has an owner, a due date and a re-test, nobody is named as a cause, and the facilitator has asked every participant whether the record is accurate. Limiting the output to three changes is deliberate: a review that commits to twelve closes four and forgets eight.
AI in the review
AI can help with a review in four ways: it can assemble a timeline from logs and case entries, it can compare the incident with earlier reviews to find recurring conditions, it can draft the narrative from the evidence pack, and it can propose changes to detections and playbooks as draft pull requests. These are tasks of the kind the earlier chapters assign to Mode 1 to Mode 3 tools and to SOC agents, and each is useful because the review is otherwise assembled by tired people at the end of an incident.
The danger lies in the output being fluent. A generated review has a clear timeline, a plausible set of contributing factors and a tidy list of actions, and it can be produced in the time it takes to ask. The research on human use of automation describes why that is a risk for the reviewers: people who rely on an automated aid tend to under-check it, and the effect is documented as complacency and automation bias (76, Parasuraman & Manzey, 2010). Bainbridge's analysis of automation points to the same structure: when automation takes the routine part of the work, the human is left to monitor it and is given less practice at the very skill on which monitoring depends (75, Bainbridge, 1983). Applied to review, the routine part is the reconstruction of events, which is also how junior analysts learn how incidents unfold. A team that never reconstructs a timeline by hand loses both the check on the draft and the training. This is an application of the cited findings to the review, and it is the book's own conclusion, not a measured result for review.
Five rules keep the review honest.
- The evidence pack is the authority, the draft is a view of it. The model may read the pack and nothing else. A statement in the draft without a pointer to the pack is struck out before the meeting.
- People correct the timeline in the room. The walk through the timeline is not skipped because a draft exists. The corrections are counted, and a draft that needs no corrections over several reviews is a signal to seed an error and see whether it is caught (Chapter 14).
- The record states what was drafted. The review record lists which sections an AI system drafted, under which mandate manifest, and who verified them. This is the same traceability that the case record carries for investigations.
- AI proposes changes, people choose them. A proposed detection change arrives as a draft pull request at Level 1 Assisted. The choice of the three changes, and the choice of what not to change, belongs to the review.
- The review is not a performance assessment. Pattern-finding across reviews is done on conditions (a data source, a playbook step, a handover) and never on individual analysts. Where a SOC tool can log analysts' queries and actions, the use of that log in a review is governed by the works agreement, and a review that would rank analysts is outside it. Nordvik's union has negotiated that measures are never reported by name, and Hansa's works council co-determines under the group agreement.
The design recommendation is to keep case records and reviews as structured data from the start, because pattern-finding across many reviews needs a corpus. Speculation. A review process that proposes, approves and deploys its own changes with no person in the loop is speculation; the Level 2 ceiling on changes to detections and playbooks in the table at the end of this chapter exists to keep it out of the design.
The finding-to-control path
A finding is a statement that a control, a detection, a playbook, a mandate, a contract term or a skill did not hold in a stated condition. The path from finding to verified control has six stages, and the diagram in Figure 11.1 shows them: incident or exercise, finding, change, re-test, verified control, and back to the register if the re-test fails.
| Stage | What exists at the end | Owner |
|---|---|---|
| Finding opened | An entry in the finding register with source, affected artefact, condition and severity | The review facilitator, within one working day |
| Owner and date | A named role, a due date and the re-test defined in advance | The SOC lead |
| Change made | A merged pull request or a signed change to a contract, mandate or runbook | The artefact owner |
| Re-test run | The recorded result of a test that re-runs the original scenario | The pipeline, or the purple exercise |
| Finding closed | Closure recorded with a pointer to the passing re-test | The artefact owner; the pipeline where the re-test is codified |
| Control classified | The related control is marked verified, declared or failed | The control owner |
Three rules from the earlier volumes apply without exception. A finding is not closed because the change was merged, but because the re-test passed; this is the rule of AI Red Team, Chapter 26. A control that has never been re-tested is declared, not verified, in the classification of AI Threat, Chapter 30. And where two controls fail together because they share a dependency, the finding records the shared dependency, because the control-to-threat coverage matrix of that chapter counts them as one (65, Nordqvist, 2026).
The re-test is designed when the finding is opened, not when the change is merged, for a practical reason: a re-test written after the fix tends to test the fix. For a detection the re-test replays recorded telemetry or runs a simulation through the detection record's test cases (Chapter 6). For a playbook it is a scenario run in the pre-production environment and, for the stop path, a timed drill (Chapter 10). For a contract term it is an evidence request or a rehearsal that the provider must pass. For a change to a mandate manifest it is a policy test showing that the action is refused at the policy decision point that sits outside the model. Findings that cannot be re-tested are marked as such and carry a compensating review date, because a finding that cannot be closed by test will otherwise be closed by statement.
The register is a file in version control. It is not a ticket queue that only the SOC lead can read, because the point is that anyone can see the age of every open finding, and because auditors and supervisors can be answered from it. DORA's incident-management provisions (Articles 17 to 19) and NIS 2's reporting provisions (Article 23) require an organisation to manage and report incidents (2, European Union, 2022) (3, European Union, 2022). The register is the evidence that what was learned from the incident led to a change, which is also the evidence a supervisor will ask for. The organisational implication is that the review record should hold the regulatory facts (what was reported, when and to whom) next to the technical ones.
Worked example: Post-incident review PIR-HM-0455
Illustrative. The record below is a trimmed version of the review of the incident of 2027-04-12 at Hansa Mutual's Polish service centre, recorded in Chapter 10 as INC-HM-2027-0455. Two isolations were made that night. Action A1, on workstation WS-PL-0518, ran at Level 3 Bounded under playbook PBK-HM-ISOLATE-01. Action A2, on a shared claims-settlement host, was proposed by the investigation agent HM-SEC-001 outside the playbook and approved at Level 2 in 38 seconds. The shift lead stopped the agent and released A2, because the host was running a legitimate software distribution. The review produced three findings, each with a re-test. One of them comes from a drill and not from the incident, and the record says so.
id: PIR-HM-0455
incident: INC-HM-2027-0455
case: CASE-HM-0455
organisation: hansa-mutual
review_held: 2027-05-06
facilitator_role: detection-engineering-lead
participants:
  - shift-lead-polish-service-centre
  - senior-analyst
  - agent-operator
  - detection-engineer
  - employee-representative-observer
drafted_by_ai:
  sections: [timeline, contributing-conditions]
  mandate: MND-HM-SOC-02
  verified_by: facilitator
timeline_corrections: 3
blame_assigned: false
findings:
  - id: FND-HM-0455-1
    source: incident
    condition: "Detection fired on a legitimate rollout step of change CHG-PL-2291; it did not know the change calendar"
    change: "Take the change calendar as a suppression and corroboration input; add a negative test case"
    artefact: DET-HM-0455
    version_after: 1.5.0
    owner: detection-engineering-lead
    due: 2027-06-04
    retest: "Replay recorded rollout telemetry with the change in the calendar; detection must not trigger isolation"
    retest_passed: 2027-05-27
  - id: FND-HM-0455-2
    source: incident
    condition: "Playbook v1.2.0: the two corroborating signals for A1 shared a data path"
    change: "Corroboration requires two sources on independent data paths"
    artefact: PBK-HM-ISOLATE-01
    version_after: 2.1.0
    owner: playbook-owner
    due: 2027-06-04
    retest: "Scenario run with two sources on one path; isolation must be refused"
    retest_passed: 2027-06-01
  - id: FND-HM-0455-3
    source: drill-2027-04-27
    condition: "Stop drill took 3 minutes 40 seconds against a 2 minute target; the stop control sat on the duty analyst's console only (the stop on the day took 57 seconds)"
    change: "Put the stop control on the shift lead console"
    artefact: PBK-HM-ISOLATE-01
    owner: soc-lead
    due: 2027-06-18
    retest: "Timed stop drill; must complete within 2 minutes"
    retest_passed: 2027-06-03
    retest_result: "1 minute 46 seconds"
decision: AIDR-0771
status: closed
closed_on: 2027-06-03
Three features of the record matter more than its detail. The second finding names a shared dependency between two signals that looked independent, which is the condition AI Threat, Chapter 30, tells the team to look for. The third finding comes from a drill held two weeks after the incident, not from the incident, whose own stop took 57 seconds; a review that mixed the two without saying so would make the incident look like a failure it was not, and would hide that the drill found a weakness the incident did not. Its re-test is a timed drill, not an inspection. And the closure date of the review is the date of the last passing re-test, not the date of the meeting.
The purple loop
Red findings are the best raw material a blue team gets, because they arrive with an adversary's path already worked out. AI Red Team defines red team as the team that emulates the adversary, blue team as the team that defends and purple team as the joint loop between them. This chapter concerns the blue team's side of the loop: what the SOC does with an exercise result.
An exercise, such as a threat-led test under the ECB's TIBER-EU framework (12, ECB, 2025), a quarterly purple exercise, a campaign of AI red teaming or a breach-and-attack simulation, gives the blue team a list of techniques that were tried, the telemetry each produced and whether a detection fired. The blue team's work is to turn that list into four kinds of change. First, a missing detection becomes a detection record mapped to the ATT&CK technique it covers (9, MITRE, n.d.). Second, a detection that fired but was closed becomes a finding against triage, which is a finding about a class or a threshold, not about an analyst. Third, a detection that fired and was not acted on in time becomes a finding against the playbook or the rota. Fourth, a defensive technique that the team already has but did not use can be mapped through D3FEND (11, MITRE, n.d.), which helps to say which countermeasure would have changed the outcome.
The loop then runs backwards into the tests. Every detection built from an exercise carries the exercise's scenario as a regression test, so that a later change that silently weakens the detection fails the pipeline. This is the continuous form of the purple exercise: the scenario that was run once by people is now run on every change by a harness. It is also what separates a purple loop from a set of exercise reports. A report records that a technique was missed. A loop leaves behind a test that the technique will not be missed again, and a record of the date on which that was last shown.
Chaos experiments extend the loop to the capabilities around the detection. AI Red Team, Chapter 25, set out security chaos engineering as the continuous verification of security capabilities by injecting a condition and checking a steady-state hypothesis, with safety boundaries around the experiment (64, Nordqvist, 2026). The practice descends from the chaos engineering of Netflix and its published principles, which state a hypothesis about steady state, vary real-world events and minimise the blast radius (59, Basiri et al., 2016) (60, Principles of Chaos Engineering community, n.d.), and it was adapted for security by Rinehart and Shortridge (58, Rinehart & Shortridge, 2023). For the blue team the useful experiments are the ones that test its own machinery: a log source that goes silent, a SOAR connector that fails, the isolation of a host whose rollback is then exercised, the stop path of an agent. Each result is a finding in the register with its re-test, and the experiment becomes the re-test.
Who owns the loop matters as much as how it runs. The default in this book is that the detection engineering lead owns the loop for detections, the playbook owner for playbooks, the agent operator for mandates, and the SOC lead for the register as a whole. Where there is no detection engineer, as at Nordvik, the owner of the loop is the person who owns the rules; the point is that one named role is accountable for the age of the register, and the red team or the external tester is accountable for the quality of the findings, not for their closure.
Observable. Threat-led testing under frameworks such as TIBER-EU, and chaos engineering as a published practice, are documented (12, ECB, 2025). Expected. AI Red Team, Chapter 25, describes AI-planned experiments, in which a model proposes the scenario, the hypothesis and the safety boundaries for review while narrow, deterministic actuators carry them out without the model holding estate credentials (64, Nordqvist, 2026). Speculation. Defences that tune themselves from every experiment without a human review of the change are speculation, and the design rule is that they stay so.
Detection debt and playbook debt
Detections, playbooks and mandates age. The data source changes its schema, the adversary's technique shifts, the business launches a service that the detection never saw, a model is replaced and the agent's behaviour moves with it. A detection that nobody has tested for a year is not a control. It is a belief.
Detection debt is the gap between the detections the team believes it has and those it can show work: rules that have no owner, no test case, a review date in the past or a data source that has changed since the last pass. Playbook debt is the same for response: manifests whose rollback has not been exercised, whose stop path has not been timed, or whose approvers have left. The same applies to mandates, whose review dates and permissions drift away from the work the agent does now. The word debt is chosen with care: it is incurred knowingly, it accrues interest in the form of missed events and unreliable alerts, and it is repaid by scheduled work, not wished away.
Treat the debt as a register with owners and ages, held beside the finding register or as a view over it. Each entry has the artefact, the kind of debt (no owner, no test, stale data source, overdue review, untested rollback), the date it was first recorded, the owner and the planned repayment. Four defaults keep it honest.
| Debt | Default threshold | Default consequence |
|---|---|---|
| Detection without an owner | 30 days | Disabled or moved to the provider's default set, recorded as a decision |
| Detection without a passing test case | 90 days | Marked declared, not verified, in the control catalogue |
| Playbook rollback or stop path not exercised | 180 days (two missed quarterly drills, Chapter 10) | Autonomy ceiling drops one level until exercised |
| Mandate past its review date | 0 days | The agent's permissions lapse at the policy decision point |
The thresholds are defaults, and a team of six, as at Nordvik, will set longer ones than a team of 38, as at Hansa. The rule that does not bend is that the debt is visible, with an age, and that an expired mandate does not keep running. A mandate that lapses by policy, enforced outside the agent, makes review an event that must happen, not a calendar entry that may be missed.
AI is useful here, and the use has a limit. An assistant can scan the repository for detections without owners or tests, draft the missing test cases and propose retirements for rules that have not fired and whose data source is gone. Those are Level 1 Assisted drafts. AI also creates debt faster than people do: if a detection-engineering assistant drafts rules from threat reports at the pace a model can write, the team's capacity to review, test and maintain them does not grow with it. The pipeline should therefore refuse a rule that arrives without its test case, whoever or whatever drafted it.
Learning across boundaries
A blue team learns from its own incidents and from everyone else's, and it owes the same in return. There are four boundaries.
Between teams in the organisation. The finding that matters to the SOC often belongs to someone else: a platform team that owns the log pipeline, an application team whose service lacks audit logging, an identity team. The finding goes to the register with that team as the owner, and the SOC lead's job is to keep it visible. Where the fix is a design change, the finding reaches the security architect as a requirement for the boundary, the log source or the control catalogue.
Between the organisation and its providers. A managed provider's detections and AI are part of the blue team's estate. Lessons from a review become contract changes: notice of model change, sampling of closed alerts, who owns detection content, paging times. The review record therefore lists provider-side findings separately and sends them through the contract's change procedure, with an evidence request as the re-test.
Between organisations. The CSIRT network, sector groups and information-sharing arrangements exist so that one organisation's lesson protects the next. NIS 2 Article 23 sets reporting to the national CSIRT or competent authority, including a final report (3, European Union, 2022), and DORA Articles 17 to 19 do so for major incidents at financial entities (2, European Union, 2022); Chapter 19 maps them. The architectural implication is that the review record should hold a sharing-ready section from the start, with the indicators, techniques and detection logic that can leave the organisation separated from what cannot. Indicators can travel as STIX objects over TAXII (22, OASIS Cyber Threat Intelligence (CTI) TC, 2021), and detection logic in a vendor-neutral format such as Sigma (27, SigmaHQ, n.d.).
Between the review and the people. Personal data appears in review records: names of staff, of affected customers, of residents. Where an incident involved a personal data breach, the notification duties of the GDPR (Articles 33 and 34) apply and the EDPB guidelines on breach notification set out how they are read (8, European Union, 2016) (79, EDPB, 2023). The shared version of a review therefore removes names and customer data, and the sharing agreement states how the receiver may handle what it gets. Sharing never extends to the analysts' own performance data.
The review pack is classified with the incident, and AI that reads it runs on the routes Chapter 12 sets out for sensitive alert data.
Measuring learning
A blue team's time to detect and time to respond can be improved by closing alerts faster, which says little about the quality of its judgement. Learning supplies measures that are hard to improve by speed alone.
Four measures work, and each has a way of being gamed that the design must anticipate.
| Measure | What it shows | How it is gamed | Counter-measure |
|---|---|---|---|
| Time from finding to verified control (median and 90th percentile) | How quickly the team closes a gap | Closing by statement, or splitting findings | Closure requires a passing re-test; severity is set at opening |
| Recurrence rate (findings in a class that return within 12 months) | Whether fixes held | Reclassifying a repeat as new | Classes are fixed in the register schema; repeats are linked |
| Share of controls verified, declared and failed | How much of the defence is shown to work | Declaring and never testing | The date of the last passing re-test is part of the record |
| Age of the oldest open finding and of the debt register | Whether the backlog is managed | Closing the oldest first and ignoring severity | Report age by severity band |
The measures are reported for the team and for the artefact classes, never for individuals, which is also what the union at Nordvik and the works council at Hansa have agreed in substance. A number of findings opened is not a measure of learning, and neither is a number closed; both can be raised by splitting and ticking. What matters is whether the same condition returns and how long a known gap stays open with the test not passed. AI Red Team reports recoverability beside patch velocity in management reporting (64, Nordqvist, 2026); time from finding to verified control belongs beside time to detect and time to respond for the same reason, since it measures what the first two cannot: whether the team is getting better.
Across the degrees of delegation
The table sets the default ceilings for the learning loop. The mode describes how the AI is deployed and whose identity it uses; the level describes who decides each action. None of the actions here is irreversible in the B4 Respond sense, and none decides about a named person's access to work.
| Activity | Usual mode | Default ceiling | Condition |
|---|---|---|---|
| Draft the timeline and narrative from the evidence pack | Mode 1 or Mode 2; Mode 3 with a mandate | Level 1 Assisted | Pack only; corrections made in the room; sections marked as drafted |
| Compare the incident with earlier reviews to find recurring conditions | Mode 3 or Mode 4 | Level 1 Assisted | Conditions, not individuals |
| Propose a change to a detection or playbook as a pull request | Mode 3 or Mode 5 agent with a mandate | Level 2 Supervised | A detection engineer or playbook owner approves; no direct deployment |
| Open a finding in the register from a failed pipeline test | Mode 5 agent | Level 3 Bounded | Codified rule; reversible; owner assigned by rule |
| Close a finding on a passing codified re-test | Pipeline with an agent | Level 3 Bounded | Not for findings on a stop path or a containment; those need a person |
| Plan a chaos experiment | Mode 3 or Mode 4 | Level 1 Assisted | Plans only; no estate credentials; a person approves the safety boundaries |
| Execute a catalogued experiment | Deterministic actuator | Level 3 Bounded | Inside the catalogue, with abort and stop path outside the system under test |
| Retire a detection with no owner and no source | Agent | Level 2 Supervised | Recorded decision; reversible by revert |
Nordvik Region and Hansa Mutual
Nordvik Region. The Region's reviews are written for the audit committee and for the provider, and the learning that matters is rarely a change to a rule. The senior security analyst, Karin Lund, writes the review; the findings that follow are changes to the provider's practice and the contract and, from this chapter's point of view, to detection ownership: a rule the Region owns has a named owner and a test, and a rule the provider owns is covered by an evidence request. Its first reviews showed that a class of low-severity alerts was closed out of hours by the provider's AI under no stated rule, which the Region recorded as a provider-side finding and carried into annex MS-2 (Chapter 16). The Region's register is small, a file in the AI platform repository, and its re-tests are mostly evidence requests and the quarterly injected test of annex MS-1. With six analysts, there is no slack for large exercises, so the Region reuses the annual penetration test and the injected test as its purple loop and keeps its debt thresholds long. Review records are written to survive public-access requests, which leads the team to separate the shareable summary from the classified pack at the outset.
Hansa Mutual. The group SOC runs a purple exercise every quarter with the red team of five and the detection-engineering team of four, and keeps a finding register in the repository. Reviews are facilitated by a detection engineer, and the shift leads at the Polish service centre and in Hamburg attend. The register feeds the dashboard of verified, declared and failed controls that the group already reports from the catalogue. Hansa's risk is not too few reviews but too many drafted rules: the detection-engineering team of four must not be buried by the output of HM-SEC-002 and the new agents, so its pipeline refuses a rule without its test case and its debt register has short thresholds. The Konzernbetriebsrat has agreed that review records do not carry measures by person, and the SOC annex to the group works agreement of 2027 records the use of analysts' query logs in reviews. The difference between the two is the one the book keeps returning to: Nordvik learns mainly through contracts and the few rules it owns, Hansa through code and a pipeline, and both close findings only on a passing re-test.
Summary
This chapter treated B5 Learn, and the parts of B2 Detect and B4 Respond that a review changes. A post-incident review is engineering: blameless, evidence-based and ending in changes to code that have owners, dates and re-tests. The 90-minute method in this chapter limits a review to three committed changes so that they get done.
AI helps by assembling timelines, finding recurring conditions and drafting changes, and it creates a new failure: a fluent review that nobody checked. The remedy is to keep the evidence pack as the authority, to correct the timeline in the room, to record which sections were drafted and to keep AI proposals at Level 1 Assisted or Level 2 Supervised until a person has chosen. The finding-to-control path, the purple loop and the chaos experiments of AI Red Team are the machinery of learning, and the rule that holds them together is that a finding is closed when the re-test passes and not before.
Detections, playbooks and mandates decay, and the debt register makes that visible with an age, an owner and a consequence. Learning continues across the boundaries of teams, providers and organisations, under the reporting duties of NIS 2 and DORA and with personal data removed from what is shared. Learning is measured by the time from finding to verified control, the recurrence of conditions and the share of controls verified, reported for the team and never for the individual. Two conclusions follow from the chapter. The rate of new detections is bounded by the rate at which the team can test them. And the number of findings opened or closed is not a measure of learning, because both can be raised by splitting and ticking; what matters is whether the same condition returns and how long a known gap stays open with its test not passed. The reader can begin by opening the last incident review and checking whether each finding has a re-test and a date.
Chapter 12 turns from the loop to the analyst's own use of AI in Modes 1 to 3, and to the policy that makes that use safe with sensitive data.
Sources
- European Parliament and Council of the European Union (2022). Regulation (EU) 2022/2554 on digital operational resilience for the financial sector (DORA). Official Journal of the European Union. (2, European Union, 2022)
- European Parliament and Council of the European Union (2022). Directive (EU) 2022/2555 on measures for a high common level of cybersecurity across the Union (NIS 2 Directive). Official Journal of the European Union. (3, European Union, 2022)
- European Parliament and Council of the European Union (2016). Regulation (EU) 2016/679 (General Data Protection Regulation). Official Journal of the European Union. (8, European Union, 2016)
- MITRE Corporation. MITRE ATT&CK: Adversarial Tactics, Techniques, and Common Knowledge. (9, MITRE, n.d.)
- MITRE Corporation. MITRE D3FEND: A knowledge graph of cybersecurity countermeasures. (11, MITRE, n.d.)
- European Central Bank (2025). TIBER-EU: Threat Intelligence-Based Ethical Red Teaming framework. ECB. (12, ECB, 2025)
- NIST (2024). The NIST Cybersecurity Framework (CSF) 2.0. NIST CSWP 29. (17, NIST, 2024)
- National Institute of Standards and Technology (2025). Incident Response Recommendations and Considerations for Cybersecurity Risk Management: A CSF 2.0 Community Profile. NIST SP 800-61 Rev. 3. (19, NIST, 2025)
- OASIS Cyber Threat Intelligence (CTI) TC (2021). STIX Version 2.1 and TAXII Version 2.1. (22, OASIS Cyber Threat Intelligence (CTI) TC, 2021)
- SigmaHQ. Sigma: Generic Signature Format for SIEM Systems. (27, SigmaHQ, n.d.)
- Rinehart, A. & Shortridge, K. (2023). Security Chaos Engineering: Developing Resilience and Safety at Speed and Scale. O'Reilly Media. (58, Rinehart & Shortridge, 2023)
- Basiri, A. et al. (2016). Chaos Engineering. IEEE Software 33(3). (59, Basiri et al., 2016)
- Principles of Chaos Engineering community. Principles of Chaos Engineering. (60, Principles of Chaos Engineering community, n.d.)
- Nordqvist, G. (2025). Architecture as Code. The Architecture as Code Series, Book 1. (61, Nordqvist, 2025)
- Nordqvist, G. (2026). AI Red Team: AI as an Active Part of Cyber Defence in European Enterprises and Public Authorities. The Architecture as Code Series, Book 4. (64, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Threat: Are the Dystopias Coming True? Evidence, Risk and Response for European Enterprises and Public Authorities. The Architecture as Code Series, Book 5. (65, Nordqvist, 2026)
- Bainbridge, L. (1983). Ironies of Automation. Automatica 19(6). (75, Bainbridge, 1983)
- Parasuraman, R. & Manzey, D. H. (2010). Complacency and Bias in Human Use of Automation: An Attentional Integration. Human Factors 52(3). (76, Parasuraman & Manzey, 2010)
- European Data Protection Board (2023). Guidelines 9/2022 on personal data breach notification under GDPR, version 2.0. (79, EDPB, 2023)
- European Parliament and Council of the European Union (2025). Regulation (EU) 2025/38 (Cyber Solidarity Act). Official Journal of the European Union. (80, European Union, 2025)