Threat Hunting Transformed: Hypotheses, Data and Agents
Threat hunting is the hypothesis-driven search for intruders that the detections missed. This chapter describes what happens to it when AI proposes hypotheses, drafts and runs queries and clusters anomalies, and it argues that the hunter's scarce contribution is judgement about which hypotheses deserve the data, the compute and the analyst's week. It covers the hunt record, the conversion of findings into detections, the discipline that a hunt which finds nothing still produces a coverage statement, and the risks that come with the new tools: generated queries that are costly or wrong, over-trust in anomaly rankings, and hunts that drift from the threat to the data. It concerns two of the five blue team functions: B1 Anticipate, because a hunt starts from intelligence and from an honest view of where the organisation is exposed, and B2 Detect, because a hunt's lasting product is a detection that did not exist before.
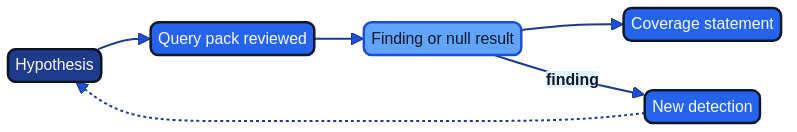
Figure 9.1: A hunt from hypothesis to query, finding, detection and coverage statement.
The chapter builds on the finding-to-control discipline of Architecture as Code (Chapter 9C), where threat handling lives in the codebase and findings return as pull requests (61, Nordqvist, 2025), and on AI Red Team, Chapter 26, where every finding from an exercise, a campaign or an incident ends as a verified control, closed only when the re-test passes (64, Nordqvist, 2026). It also takes over the conclusion of The Transformed Security Architect, Chapter 14, that reviewing what AI proposes requires independent reproduction and review that does not start from the AI's answer (66, Nordqvist, 2026). Chapter 5 supplies the hypotheses, Chapter 6 receives the detections and Chapter 11 closes the loop in the purple exercise.
Hypothesis-driven hunting
A hunt starts from a statement that can be false. In this book a hunt is a bounded, time-boxed search of defined data for evidence of a named adversary behaviour, started from a hypothesis, run by a named threat hunter and recorded so that the result can be reviewed and repeated. "Look for anything unusual in the identity logs" is not a hypothesis. "A service account used by the claims export job has been used from a host that is not part of the export job's host set, within the last 90 days" is one, because a query can show it to be true or leave it unsupported.
Hypotheses come from three places. The first is intelligence: a report describes how an adversary uses valid accounts to move between systems, and the hunter asks whether that behaviour is present in the estate. Chapter 5 describes how intelligence records are converted into hypotheses with a named reviewer. The second is an incident or a near miss: the post-incident review of Chapter 11 asks what else the intruder could have done and whether any of it happened elsewhere. The third is exposure: a system that is internet-facing, holds personal data and has thin telemetry is a better place to look than one that is none of these. All three are forms of B1 Anticipate.
Every hypothesis names a behaviour, preferably by technique in MITRE ATT&CK (9, MITRE, n.d.), the data that would show it, and the population it covers. The stolen service-account credential used in this chapter's worked example maps to T1078 Valid Accounts and, for accounts in a directory, to the sub-technique T1078.002 Domain Accounts. The mapping is not decoration. It lets the coverage statement later in the hunt say which techniques were searched for, in which data, over which period, and it lets the detection engineering team see whether a detection already exists for the same behaviour.
What AI changes in who forms hypotheses
Before AI, the hypotheses in most teams came from the one or two people who read the reports and knew the estate. AI changes the supply, not the demand. A model that reads a threat report and the organisation's asset inventory can propose far more candidate hypotheses than a hunter can rank. The proposals are cheap; the hunt that follows is not. A hunt costs query time, data-platform capacity and the attention of a person who can read the results. The hunter's work therefore moves from generating hypotheses to ranking them: which few of the many are worth four weeks, given what the organisation holds, what its adversaries have been seen to do and what its existing detections already cover.
That ranking is where judgement sits, and it is where the tools are weakest. A model can ground a candidate in a report and in an asset list. It cannot know that the Polish service centre migrated its batch scheduler last quarter and that every service account's host set therefore changed, or that the hunt would be cheap on one data source and ruinous on another. The rule for this book is that an AI-proposed hypothesis is a draft at Level 1 Assisted, and the hunter who adopts it owns it, records its source as AI-proposed, and states why it was ranked above the others. Chapter 5 tests the grounding of AI-extracted intelligence; the hunter repeats the test for any claim in the hypothesis that the hunt depends on.
Agents as hunting assistants
The assistants a hunter uses fall into three groups, and the usage modes of AI Governance and AI Platform and Security, Chapter 2, say what each can touch.
The first group drafts. A conversational or embedded assistant (Modes 1 and 2), or an agentic work tool (Mode 3), turns a hypothesis into a candidate query in the query language of the SIEM or the data lake, explains an unfamiliar log source or translates a query between platforms. It acts with the hunter's own identity, so it can read what the hunter can read and nothing more. The second group clusters and ranks. A Mode 4 service groups similar events, flags outliers and orders them by a score. The third group runs. A Mode 5 hunting agent has an identity of its own, read-only permissions and a mandate manifest, and executes query packs that a person has approved, on a schedule, returning results for a hunter to read.
Four properties of this work shape the design.
Generated queries are code and are reviewed as code. A query that is syntactically valid can still be wrong in ways that matter: it filters on a field that is empty for half the sources, joins on a key that duplicates rows, or reads a time window in the wrong zone. A wrong query produces a confident null result, which is the most dangerous output a hunt can give. A query can also be costly: an unbounded join over ninety days of identity and endpoint telemetry can occupy the platform that the SOC needs for live detection. The review of a generated query therefore asks two questions before the first run: does it test the hypothesis, and what will it cost. The practical guide below gives defaults.
Anomaly rankings are leads, not findings. Clustering and outlier scores order events by how unusual they are in a statistical sense. Unusual is not the same as malicious, and a ranking built on the organisation's own history inherits that history's blind spots: an intruder who has been present for months is part of the baseline. The documented tendency of people to rely on automated aids, and to check them less when they appear reliable (Chapter 11), is a reason to design against over-trust rather than to hope for vigilance. In practice the hunter reads the underlying events behind the top-ranked cluster and a sample from below the line, and records both.
The data may be written by the adversary. The question this book asks in Chapter 1 is how an analyst can verify what AI concludes when the evidence it reads may be written by the adversary. A hunting agent reads log fields that an adversary can influence: a user-agent string, a file name, a ticket comment, a hostname. Where a model reads that text, the text can try to instruct it, and AI Platform and Security, Chapter 16, concluded that this is a property of the architecture, not a defect to be patched (63, Nordqvist, 2026). The control is outside the model: the hunting agent's identity is read-only, its tools are limited to the approved query pack and the result store, and it has no path to change the estate whatever it reads. OWASP's list of risks for agentic applications gives the shared vocabulary for the failure modes a mandate has to bound (14, OWASP, 2025).
No hunting agent changes the estate. A hunt looks; it does not touch. The agent that finds a suspicious account does not disable it. It writes a finding to the hunt record and, if the hunter confirms, a case is opened and the response follows the playbook rules of Chapter 10. This keeps the hunting agent at a level where the question of reversibility never arises, and it keeps the decision about a named person's account with a named human decider.
The hunt record
A hunt that lives in a hunter's notebook cannot be reviewed, repeated or counted. The hunt record (HNT-*) is the versioned artefact that holds a hunt: the hypothesis and its source, the ATT&CK technique, the data sources and the period, the query pack with review status and cost, the result, the findings, the coverage statement and the conversion target. It lives in the repository beside the detection records of Chapter 6, and it is reviewed by pull request. Hunt records use the identifiers HNT-NR-* for Nordvik Region and HNT-HM-* for Hansa Mutual.
Three fields carry the weight of the record.
The query pack is a list of queries, each with an owner, a status (draft, reviewed, approved), the reviewer's name, a cost estimate and the data source it reads. A query is approved only after a person other than its drafter has read it, run it against a small sample with a known answer and recorded the cost. An AI-drafted query that has not passed this review is a draft and is not run against the full estate.
The result states what was found in terms of events, not conclusions: how many events matched, how many were examined by a person, how many were explained and by what. A cluster of matching events that a hunter has read and explained as a migration script is recorded as explained, with the explanation and the person who gave it.
The coverage statement says what the hunt covered and what it did not: which hosts, accounts and log sources, which period, which technique and which variants of the technique were not searched for because the data does not exist or was too costly to query. The section on null results returns to it.
Worked example: hunt record HNT-HM-0031
The following record is illustrative. It shows a hunt at Hansa Mutual for the behaviour described above, in the Polish service centre, which processes claims for the German, Dutch, Swedish and Norwegian entities and therefore runs service accounts that touch several markets. The hypothesis was drafted from intelligence record INTEL-HM-0142 (Chapter 5) and adopted by a named hunter.
# hunts/HNT-HM-0031.yaml (illustrative)
id: HNT-HM-0031
version: 1.1.0
status: closed
owner: hunter-hm-02
hypothesis:
  statement: >
    A service account of the claims export job at the Polish service centre
    has been used from a host outside the job's registered host set during
    the hunt period.
  source: INTEL-HM-0142
  proposed_by: ai-assisted        # HM-SEC-002 draft, Level 1 Assisted
  adopted_by: hunter-hm-02
  ranked_above: [HNT-HM-0033, HNT-HM-0034]
  attack: [T1078.002]
scope:
  data: [idp-signin, edr-process, claims-adapter-audit]
  period: 2027-02-01/2027-04-30        # two four-week cycles inside a standing hunt
  cycles:
    - {opened: 2027-02-15, closed: 2027-03-15, outcome: gap found, requirement handed over}
    - {opened: 2027-04-05, closed: 2027-04-30, outcome: approved queries repeated on the extended period}
  markets_in_scope: [DE, NL, SE, NO]   # data stays in the EU/EEA region
query_pack:
  - {id: Q1, reviewer: hunter-hm-03, status: approved, est_cost_units: 40}
  - {id: Q2, reviewer: hunter-hm-03, status: approved, est_cost_units: 85}
  - {id: Q3, reviewer: hunter-hm-01, status: rejected,
     note: join duplicated rows; rewritten as Q3b}
result:
  matched_events: 214
  read_by_person: 214
  explained: 211
  explanation: scheduler migration of 2027-03-09, change CHG-PL-2291
  unexplained: 3
  disposition: 3 events opened as CASE-HM-1311, closed benign after owner check
coverage:
  searched: [service accounts in group SVC-CLAIMS-EXPORT, 41 accounts]
  not_searched: [service accounts outside the group, 118 accounts]
  data_gap: no host-level logon telemetry on 9 legacy file servers
  technique_variants_not_covered: [T1078.004]
conversion:
  detection: DET-HM-0455
  gap_found: no detection for service-account use from a host class outside its registered set
  detection_test_passed: 2027-04-02    # before the detection went live
  repeat_by: 2027-08-31
review: {reviewer: lead-hm-detection, date: 2027-05-12}
The record is short because the discipline is specific. The first cycle ended with a requirement, the detection was tested and live before the second cycle, and the record was closed only after both. It names who proposed the hypothesis and who adopted it. It shows that a query was rejected on review and rewritten. It says that 214 events were read by a person, not summarised by a model. It records that the hunt found no compromise, and it still produced a gap, the absence of a detection, and a coverage statement that includes nine legacy file servers the hunt could not see. The next section follows the conversion.
From finding to detection
A hunt finds one of three things: a compromise, a benign explanation or a gap. The first opens a case and a response under Chapters 7, 8 and 10. The second closes the lead. The third is the one that matters most for B2 Detect, and it is the most common: the behaviour the hunter searched for would not have raised an alert, because no detection covered it, or the detection existed but did not fire on the data. A hunt is, in this view, a way of finding detection debt by looking at the places where an alert should have been.
The conversion has a fixed path. The hunter writes the hunt's logic as a detection requirement in the hunt record's conversion block. The detection engineering team drafts the detection, with AI assistance at Level 1 Assisted where it helps, in a portable format such as Sigma (27, SigmaHQ, n.d.), as Chapter 6 describes. The detection is accepted only when a test shows it fires on replayed or simulated telemetry and a measure shows its false-positive cost, and it receives its own detection record, owner and review date. In the worked example the new detection is DET-HM-0455. The hunt is not closed until the detection's test has passed, which the record shows as a date; this is the re-test rule of the purple loop (AI Red Team, Chapter 26) applied to a hunt. In the quarterly purple exercise of Chapter 11 the red team then tries the behaviour against the new detection, which is the verification that the conversion worked.
Not every finding becomes a detection. Some behaviours are too common in the legitimate estate to detect without unacceptable noise; they become a recurring hunt instead. The conversion field therefore takes one of two values, a detection identifier or a repeat date, and the hunter must name one. A hunt that ends with neither has produced an observation and not an improvement.
The conversion also feeds intelligence back. A hunt that found the behaviour absent for a technique an adversary is known to use, with a documented gap in telemetry, is a finding for the exposure view of Chapter 5: the nine legacy file servers without logon telemetry are an exposure, whatever the hunt found on them.
Practical guide: Running a four-week hunt cycle
Purpose. Run one hunt from hypothesis to a detection or a dated repeat, with a record that another hunter can review and repeat.
Roles. The threat hunter owns the hunt. A second hunter or a detection engineer reviews the query pack. The SOC lead approves the schedule and the data-platform budget. The privacy officer is consulted when the data includes personal data beyond security logs, and employee representatives are informed where the agreement requires it (see the section on cost and safety).
Steps.
- Week 1, choose and scope. Take the candidate hypotheses from Chapter 5, including AI-proposed ones. Rank them by the threat (is the technique used against organisations like ours), the exposure (do we hold the asset and the data) and the existing coverage (does a detection already exist). Adopt one, or at most two. Write the hypothesis, the technique, the data sources and the period in the hunt record. Default period: 90 days. Check that each data source exists for the whole period and note any gap now, not at the end.
- Week 1, set the budget. Agree the query cost budget with the platform owner: a total for the hunt and a ceiling per query. Default: no query runs on the full period before it has run on a seven-day sample, and no single query exceeds 10 per cent of the hunt's budget without the platform owner's agreement.
- Week 2, draft and review the query pack. The hunter, with an assistant if used, drafts the queries. A reviewer other than the drafter reads each one, runs it against a sample with a known answer, plants a known event if the platform allows, and records the cost. Approve, reject or rewrite. Record rejections; they are a measure of how often generated queries are wrong.
- Week 3, run and read. Run the approved pack. The hunter reads the underlying events, not only the cluster summary or the ranking. For any ranked list, read the top ten and a random sample of ten below the line. Record counts of matched, read and explained events. Explain every event or open a case.
- Week 4, close. Write the coverage statement. Write the conversion: a detection requirement handed to detection engineering, or a repeat date with a reason. Update the hunt record and have it reviewed by pull request.
- After the cycle. Record the hunt's measures in the team's register: hunts run, findings by type, detections converted, queries rejected on review, cost against budget.
Definition of done. The hunt record is merged with a result, a coverage statement and either a detection identifier or a repeat date. Adapt the defaults to the platform's cost model, the contract with a managed provider and, where a works agreement governs the data, its terms.
Null results
A hunt that finds nothing has not found that nothing is there. It has found that nothing was found by these queries, in this data, over this period. The difference is the content of the coverage statement. Without it, a null result reads as reassurance, and a leadership that is told "we hunted and found nothing" has been given less information than it thinks.
A good coverage statement has four parts. It lists what was searched: accounts, hosts, sources and period. It lists what was not: the populations excluded for cost, the sources that do not exist, the variants of the technique that the queries cannot see. It states the confidence the hunter has in the queries, based on how they were tested: a query that has been shown to find a planted event is stronger evidence than one that has not. And it gives a repeat condition: a date, or a trigger such as a new report on the technique or a change to the data sources.
AI makes the null result easier to produce and easier to misread. A model summary of an empty result set reads fluently and carries no information about whether the query was right. The discipline is the same as for any generated output: the hunter checks that the query could have returned a positive. Planting a known event, or replaying a captured one, in a test environment or in the sample is the strongest means; the breach-and-attack simulation and the purple exercise supply such events for the techniques they cover.
Over a year, the coverage statements accumulate into a map: which techniques have been hunted, where, when and with what confidence. This map is a useful object for B1 Anticipate because it shows where the organisation is blind and how old its knowledge is. Where a technique was last hunted eighteen months ago on data that has since changed, the map shows that, and the next hunt's ranking can use it. The MITRE D3FEND knowledge graph of countermeasures (11, MITRE, n.d.) gives a vocabulary for the defensive side of the map, so that a gap in coverage can be stated as a missing class of countermeasure and not only as a missing rule.
Cost and safety
A hunt consumes shared resources and can touch personal data. Both need rules before the first query.
Cost. The data platform that the SOC uses for live detection is also the platform a hunt queries. A query that is expensive enough to slow detection is a risk to B2 Detect. The guard is the cost budget of the practical guide, the sample-first rule and a quota on the hunting identity, whether human or agent, enforced by the platform and not by the query's author. A Mode 5 hunting agent has the same quota and, in addition, a ceiling on the number of queries per run and an automatic stop when the budget is reached. Cost per hunt, per query and per finding is recorded, because a team that cannot say what a hunt costs cannot say whether a hunt is worth running.
Data access. Security telemetry contains personal data, and in a health or social-care authority it can contain special-category data. The GDPR applies to a hunt as it does to any processing of that data (8, European Union, 2016). The hunt's scope field is the place where the legal basis, the data minimisation and the retention are recorded. A hunt reads the fields it needs, not whole records; a query that returns the content of a social-care case note to find a logon anomaly is the wrong query. Where telemetry crosses borders, as at Hansa Mutual, the market attribute stays attached to the data and the hunt respects the per-market overlays, so that an analyst or agent in one country does not read data it is not entitled to see in another.
Hunting people. A hunt for an insider, or a hunt whose queries can profile an employee's behaviour, is a different object from a hunt for a technique, and it falls within the rules examined in Chapter 8 on investigating people. Hunts in this book are for behaviours, not for individuals. A hunt that narrows to a named person stops and becomes a case, with the authorisation a case requires. The hunter's own activity is recorded by the same tools, which brings the monitoring of analysts into scope of the agreements discussed in Chapters 16 and 18.
Authorisation. Each hunt record names who authorised the scope, normally the SOC lead, and, where the data warrants it, the privacy officer. A hunt that is rerun on a schedule by an agent runs under an approved query pack with an unchanged scope; a change to the scope is a change to the record, reviewed again.
Drift. The last risk is a quiet one. A team with good tools and plentiful data starts to hunt what the data makes easy, not what the threat makes likely. A hunt that cannot name its source is a sign that the work has drifted from the threat to the data. The hunt records make drift visible: a quarter in which most hypotheses have no intelligence source, or in which every hunt searched the same log source, is a signal to the SOC lead. The remedy is the ranking step of the first week, with its three questions, applied honestly.
Across the usage modes
| Mode | What it does in a hunt | Identity and permissions | Degree of delegation | Ceiling |
|---|---|---|---|---|
| Mode 0 Ambient AI | Outlier scoring and clustering inside the SIEM or EDR product | The product's own; the team may not know the logic | Not decided by the team; treat as an unverified lead | Establish and record what it does before relying on it |
| Mode 1 Conversational assistants | Drafts queries and explains log sources | The hunter's own; no tool access | Level 1 Assisted | Draft only; reviewed before any run |
| Mode 2 Embedded workplace assistants | Drafts queries inside the SIEM console | The hunter's own | Level 1 Assisted | Draft only; platform quota applies |
| Mode 3 Agentic work tools | Drafts, runs queries on samples, summarises results | The hunter's own, with a mandate manifest | Level 1 to Level 2 Supervised | Hunter reads the events behind any summary |
| Mode 4 Built AI applications | Clusters and ranks anomalies as a service | Service identity, read-only | Level 1 Assisted | Rankings are leads; sample below the line |
| Mode 5 Autonomous production agents | Runs approved query packs on a schedule | Own read-only identity, permission manifest | Level 2 Supervised (see below) | No change to the estate; stops at the budget; a person approves the pack and reads the findings |
No hunting agent acts on the estate, so Level 4 Autonomous does not arise for hunting. Level 3 Bounded would be available for a scheduled run of an approved pack, because the run changes nothing. Hansa nevertheless keeps its hunting agent at Level 2 Supervised: a person approves the pack, its schedule and every change of scope, and reads the results before anything follows, and the queries draw on capacity that live detection shares, which the platform quota bounds. A conversion into a detection is a change to production detection content and follows Chapter 6; a response to a finding follows Chapter 10.
The hunter's craft
What remains human in a hunt is not typing queries. It is a sense for what is out of place, formed by having looked at a particular estate for long enough to know what its ordinary days look like, and by having read enough incidents to know how adversaries use ordinary things. A hunter notices that a service account's logons occur at 02:10, when the batch window closed at 01:00; that a host name follows the convention but not the numbering; that a change ticket exists and has no matching change. None of this appears in a ranking, and much of it will not be a finding. It is the source of the hypotheses worth the data.
This craft is at risk for the reason Bainbridge gave in 1983: automation removes the practice that would have prepared people for the cases it cannot handle (75, Bainbridge, 1983); Chapter 11 sets out the evidence in full. If an assistant writes every query, the hunter who never writes one loses the ability to tell when a query is wrong. The response follows The Transformed Security Architect, Chapter 14, and AI Red Team, Chapter 6: keep a share of the work unassisted, drill with seeded errors and measure the quality of review. For hunting this means three practices. A hunter writes the queries of one hunt in four without an assistant. The reviewer plants a known event, or a deliberately wrong query, in the pack and records whether the hunter finds it. And the hunter reads raw events behind every summary that matters. These are cheap, and they are the means by which hunters stay capable of supervising the tools. Chapter 23 returns to how new hunters are made when junior triage is automated.
Hunting is also where the senior and the junior analyst meet the same material. A junior analyst who joins a hunt reads real telemetry with a purpose, which is more instructive than closing alerts that a machine has already enriched. The hunt is therefore a place to keep the craft and to grow analysts, and this is a reason to protect it from automation that would leave nothing for a person to learn.
Nordvik Region and Hansa Mutual
Nordvik Region has no hunting practice at the start of the book and no intelligence analyst. Its six analysts work office hours and the provider monitors at night under framework agreement NR-2025-044. The Region hunts at most twice a year, with the provider's help, and uses each hunt as a test of the provider's detections: a hypothesis is chosen from the national CSIRT's reporting, the hunt is run, and the question is whether the provider's service would have alerted on the behaviour. The first hunt, HNT-NR-0001, searches for the abuse of a valid account against the Region's identity provider in the benefits-triage service's administration path. The hunting query pack of the unit runs at Level 1 Assisted on the Region's reserved capacity, because telemetry holds personal and health data, Karin Lund owns the hunt and a second analyst reviews every query, so that no query is approved by its drafter (AIDR-0705). A hunt that finds no alert from the provider is recorded as a finding against annex MS-2 (Chapter 16), which strengthens the Region's case for owning detection content. The decision to run a hunt programme at this scale is recorded in AIDR-0709. The limit is capacity: a hunt takes a senior analyst away from the queue for weeks, and with six analysts that is a visible cost.
Hansa Mutual hunts on a standing cadence. The threat-intelligence cell of three feeds hypotheses to the hunters, who are drawn from the senior analysts and the detection-engineering team of four, and the cadence aligns with the quarterly purple exercise run with the group red team of five. The same team of four reviews the drafts of HM-SEC-002 (Chapter 6), so the number of hunts in flight is set by the review load and not by the tooling. Approved query packs run on schedule under the hunting agent's mandate manifest MND-HM-SOC-04, read-only, at Level 2 Supervised for the reason given above; its introduction and quotas are recorded in AIDR-0762. Because telemetry from the UK and Swiss entities and from the Polish service centre crosses borders, every hunt names the markets in scope. Before a hunt reads data that can profile employees' behaviour, the Konzernbetriebsrat is informed under the SOC annex to KBV-IT-2024. The risk at Hansa is the opposite of Nordvik's: plentiful data and tooling make it easy to hunt what is easy, so the detection-engineering lead reviews each quarter's hunt records for drift.
Summary
Threat hunting is transformed in how hypotheses are supplied and how queries are drafted, run and ranked, and unchanged in what makes a hunt worth doing: a testable hypothesis, honest data, a reviewer who has read the queries, and a record that another person can repeat. AI proposes hypotheses cheaply, so the hunter's judgement moves to ranking them by threat, exposure and existing coverage. The tools are assistants at Level 1 Assisted and, for scheduled query packs, a Mode 5 agent at Level 2 Supervised with a read-only identity, a level Hansa keeps even though a scheduled run of an approved pack would qualify for Level 3. No hunting agent changes the estate, and the controls on what it reads sit outside the model.
The hunt record is the artefact that makes this work reviewable. It holds the hypothesis and its source, the reviewed query pack with costs, the result in events, the coverage statement and the conversion. A finding ends as a detection with a passing test, or as a dated repeat; a null result ends as a coverage statement that says what was searched and what was not. Both feed B2 Detect through the detection records of Chapter 6, and both feed B1 Anticipate through the map of what the organisation has looked at and how long ago.
The risks are specific. Generated queries can be wrong or costly, and a wrong query yields a confident null result. Anomaly rankings are leads, and over-trust in them is a documented tendency to design against. Hunts drift from the threat to the data unless the hunt records show where each hypothesis came from. The craft that notices what is out of place is kept by unassisted practice, seeded errors and the habit of reading raw events.
Outlook, labelled as the series requires. It is observable that AI-assisted drafting of queries and clustering of anomalies is in use in security tooling, which AI Red Team, Chapters 18 and 19, treat as part of the AI-assisted SOC and detection engineering (64, Nordqvist, 2026). It is expected, on the NCSC's assessment, that AI will almost certainly reduce further the time between disclosure and exploitation, which has already shrunk to days (32, NCSC, 2025); the assessment does not forecast hunting, and this book draws no forecast about hunting from it. It is speculation that hunting which replaces human hypotheses entirely will work, since no source of this book shows it. The author's own projections are in Chapter 24. Chapter 10 turns from looking to acting, and sets the ceilings for what a response may do and who may stop it. To begin, take one hypothesis from your last intelligence report and write its coverage statement before you run any query.
Sources
- MITRE Corporation. MITRE ATT&CK: Adversarial Tactics, Techniques, and Common Knowledge. (9, MITRE, n.d.)
- MITRE Corporation. MITRE D3FEND: A knowledge graph of cybersecurity countermeasures. (11, MITRE, n.d.)
- SigmaHQ. Sigma: Generic Signature Format for SIEM Systems. (27, SigmaHQ, n.d.)
- National Cyber Security Centre (2025). Impact of AI on cyber threat from now to 2027. NCSC Assessment, 7 May 2025. (32, NCSC, 2025)
- OWASP Foundation (2025). OWASP Top 10 for Agentic Applications for 2026. OWASP GenAI Security Project. (14, OWASP, 2025)
- European Parliament and Council of the European Union. Regulation (EU) 2016/679 (General Data Protection Regulation). (8, European Union, 2016)
- Bainbridge, L. (1983). Ironies of Automation. Automatica 19(6). (75, Bainbridge, 1983)
- Nordqvist, G. (2025). Architecture as Code. (61, Nordqvist, 2025)
- Nordqvist, G. (2026). AI Platform and Security. (63, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Red Team. (64, Nordqvist, 2026)
- Nordqvist, G. (2026). The Transformed Security Architect. (66, Nordqvist, 2026)