Conclusions: The Blue Team Transformed
This chapter judges the book's thesis against the evidence of Chapters 1 to 27, answers the twelve questions the book took up, gives the author's labelled projection of which blue team functions a person, a system or a person conducting systems should perform in 2036, and says what a reader in five roles can do on Monday. It concerns all five functions: B1 Anticipate, B2 Detect, B3 Investigate, B4 Respond and B5 Learn. It also closes the argument that the series has made since Architecture as Code, and it does so for the people who defend an organisation.
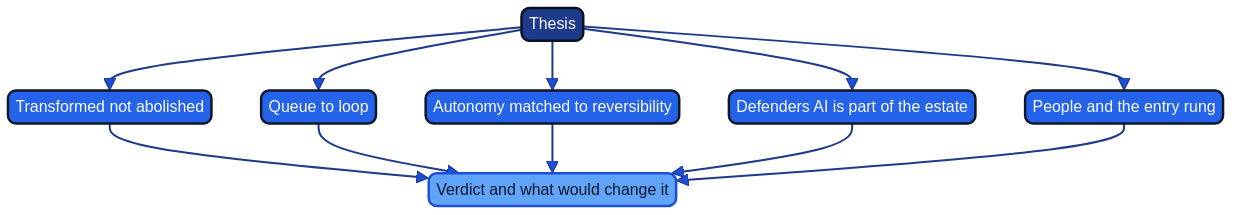
Figure 28.1: The thesis in five parts, with the evidence and the conditions that would change the view.
A word on method before the verdicts. The evidence of this book is of four kinds: research and agency sources that the chapters cite; conclusions that the earlier volumes of the series established; design reasoning of the book's own; and the illustrative cases of Nordvik Region and Hansa Mutual, who are fictional. None of it is a measured outcome from a real security operations centre (SOC) observed over several years. When this chapter says that a part of the thesis held, it means that it survived the tests that the book could apply: the literature, the instruments, the design and the worked cases. It does not mean that it is proved.
The thesis tested
The working thesis of Chapter 1 had five parts, and Chapter 1 gave each its own refutation: the evidence that would show it wrong. Each part is judged below against the chapters that tested it. A verdict is one of four: held, where the evidence available to the book supports the claim and no chapter found a counter-case; held with qualifications, where the claim survived but the book itself found cases that limit it; held in part, where a chapter refined it; and argued but not proved, where the book offers design and argument but no outcome evidence. No part earned a plain held.
| Part of the thesis | Verdict | Strongest support | What remains unproved |
|---|---|---|---|
| 1. Transformed, not abolished | Held with qualifications | Every function keeps a judgement that a person must hold and answer for (Chapters 5 to 11); duties on the management body in NIS 2 and DORA | How many people an estate needs; whether the claim survives to 2036 |
| 2. From the queue to the loop | Held in part | Detections, hunts and reviews as tested records (Chapters 6, 9, 11) | That treating alerts as evidence of missing detections reduces load; the queue did not vanish |
| 3. Autonomy matched to reversibility, stop path outside | Held with qualifications | Action classes, playbook manifests and the stop drill (Chapters 10, 13); the rule survived every application | Safety of Level 3 beyond narrow classes over years; the illustrative incident and both first stop drills found defects in implementation |
| 4. The defenders' AI is part of the estate | Held with qualifications | Architectural argument (Chapter 15); controls outside the model | Prevalence of targeted attacks on SOC agents; contract rights for provider AI |
| 5. Analysts' route and wellbeing are design questions | Argued but not proved | Research on automation and alert fatigue (Chapters 12, 14, 21, 23) | Whether the designs work; the effect of AI on load |
First part: transformed, not abolished
This part held with qualifications. Each chapter of Part II found the same structure in its function: AI takes a task, and a person keeps a judgement. In B1 Anticipate, AI extracts and correlates, and the analyst decides which verified hypotheses deserve engineering time (Chapter 5). In B2 Detect, a draft counts only when a test shows that it fires, and a named approver merges it (Chapter 6). In B3 Investigate, a conclusion that matters is reproduced from a second source before it is closed (Chapters 7, 8 and 14). In B4 Respond, a named incident commander holds the decisions that cannot be undone (Chapter 10). In B5 Learn, a finding closes only when a re-test passes, and a person chooses what to change (Chapter 11).
The legal frame points the same way. NIS 2 Article 20 and DORA Article 5 place duties on the management body, and AI Red Team, Chapter 6, concluded that responsibility does not pass to a tool (3, European Union, 2022) (2, European Union, 2022) (64, Nordqvist, 2026). The Transformed Security Architect, Chapters 1 and 27, reached the same conclusion for one role: what remains scarce is accountable human judgement, and the ability to verify and to answer for the decision (66, Nordqvist, 2026). This book extends that conclusion from a role to a team.
The qualifications are counter-cases the book found. The provider's AI at Nordvik closes alerts with no person and no stated rule (Mode 0; Chapters 7, 25 and 26), and Hansa's Level 3 classes SC-01 and SC-02 are closed unread and sampled, so "a conclusion that matters is reproduced before it is closed" holds for the conclusions a person acts on, and for the closed classes what holds is a named class owner and a sample. What is not proved is the quantity. The book shows that the work changes, that new roles grow (detection engineer, class owner, agent operator, investigation lead) and that the entry rung shrinks. It does not show how many people an estate of a given size will need, and it should not be read as a promise about headcount.
Second part: from the queue to the loop
This part held for B2 Detect and B5 Learn, and held only in part for B3 Investigate. The loop is real in the artefacts: a detection is a versioned record with a test and a review date, a hunt ends as a detection or a coverage statement, and a review ends in changes with owners and re-tests. The evidence is that this discipline is practicable, not that it is easy.
Two qualifications came out of the chapters. The first is that the queue did not disappear. Chapter 7 found that AI closes defined low-risk classes and leaves the analyst a residual queue of ambiguous and novel cases, plus the review of what was closed. The better statement of the thesis is therefore that the work moves from the queue alone to the queue and the loop. The second is that the loop can drown a team as the queue did. In the book's illustrative Hansa Mutual the drafting assistant produced 131 candidate detections in a half-year and the engineers merged 52, leaving 79 open before a cap on open drafts was added (Chapter 26). That the cap came after the queue grew supports the point more strongly than a cap designed in advance would: a loop with no cap on open drafts is another queue.
What is not proved is the premise that makes the loop attractive, that treating each alert as evidence of a detection not yet engineered reduces the load over time. Studies of SOC practitioners describe the problem, and a survey of the research treats alert fatigue as an open challenge (69, Alahmadi et al., 2022) (72, Tariq et al., 2025). They do not show that engineering detections as code cures it. That is a hypothesis of the book, which Chapter 26 tests only in an illustrative year.
Third part: autonomy matched to reversibility
This part held with qualifications, and it is the best supported of the five as a design rule. The rule survived every application the book made of it. Chapter 10 classifies response actions by reversibility and sets the ceiling by the lowest answer to five questions. Level 3 Bounded is reserved for preservation and narrow reversible actions inside a playbook enforced by a policy decision point outside the model. Wide, business-critical and person-related actions stay at Level 2 Supervised, and irreversible or external actions are taken by a named person. In none of the delegation tables of Chapters 5 to 15 does Level 4 Autonomous appear for an irreversible B4 Respond action or for an action that decides about a named person's access to work.
The qualifications are the counter-cases the book found for itself, all illustrative. In the incident INC-HM-2027-0455 the Level 3 isolation rested on two corroborating signals that shared a data path, one source seen twice (finding FND-HM-0455-2); a second isolation was approved at Level 2 in 38 seconds; and the stop took 3 minutes 40 seconds in a drill against a target of 120 seconds before it was moved and re-tested at 1 minute 46 seconds. At Nordvik the first out-of-hours stop drill failed because no one on the rota held the console role (Chapter 26). A further defect was one of decision rights: the second isolation was approved by the commander on shift, who is the deputy and not the holder of the decision, because the screen did not show the tags (Chapter 18). The rule held; each implementation needed a re-test. Because the isolation was reversible, the cost of each error was small, and because the stop path ran outside the system it stopped, the stop worked on the night. A stop path is a property that decays unless it is drilled, and it is only as good as its last test.
What is not proved is how far Level 3 can safely reach. Chapter 10 labels the extension to broader action classes with strong corroboration as expected, and unsupervised autonomous response across a production estate as speculation. No source in the book shows the escape rate of Level 3 closure or containment over years, which is why the stop rules in the mandate manifests are written as numbers that freeze delegation when a measure fails.
Fourth part: the defenders' AI is part of the estate
This part held with qualifications. The argument is structural, and it does not depend on a count of incidents. The SOC reads logs, tickets, mail, filenames and threat reports that adversaries can write, and AI Platform and Security and AI Red Team concluded that prompt injection is a property of the architecture, so that the defence is a policy decision point outside the model and permission manifests that set a ceiling on every action (63, Nordqvist, 2026) (64, Nordqvist, 2026). Chapter 15 applied that conclusion to the SOC: inputs classified by who can write them, corroboration from deterministic sources, separate reading and acting, deny-by-default egress, short-lived credentials, canaries, and the platform treated as a tier-0 asset. The consequence is the useful one for the analyst: nothing that matters should rest on the model's reading alone, so the analyst does not have to out-read the adversary. The qualification is the book's own finding FND-HM-2027-014 (severity high): in the red-team exercise the case store accepted unlabelled text and a second agent trusted a planted note, so the principle was not yet fully implemented (Chapter 26).
What is not proved is how common the threat is and whether the controls hold against a determined attacker. Indirect injection of security AI is observable in research, targeted attacks on SOC agents are expected, and the book cites no evidence of mass compromise of SOC platforms through AI, which it labels speculation. For the provider's AI, which Nordvik Region cannot inspect, the protection is contractual, and a contract right is only a promise until the first sample, seed or stop request shows that it works.
Fifth part: the route to the profession and the people
This part is argued but not proved, and it is the weakest of the five. Two of its claims are supported by well-established research. Automation leaves people the hardest residual tasks while weakening the practice they need to do them (75, Bainbridge, 1983), and people who use automated aids show complacency and bias, checking less when the aid seems reliable (76, Parasuraman & Manzey, 2010). AI Threat, Chapters 6 and 14, drew the consequence that automating junior work removes the route by which experts are made (65, Nordqvist, 2026). The designs that follow, a share of cases worked without assistance, seeded errors and incidents, caps on open proposals, rotation and apprenticeship routes, are plausible and carried over from The Transformed Security Architect, Chapter 15 (66, Nordqvist, 2026). The book has no measured outcome showing that they produce investigators who can supervise and replace the AI. On wellbeing, Chapter 21 treats the effect of AI on load as dependent on team design and not yet well measured. The book's own illustrations are not evidence, and they include a miss: Hansa's oversight record for 2027-Q3 reports an unassisted share of 0.10 against a policy of 0.20 (Chapters 14, 23 and 26). The part stands as a requirement on design, not as a result.
What the test changed in the thesis
The test changed the thesis in two ways. First, "from the queue to the loop" is better stated as "from the queue alone to the queue and the loop". Second, the implementation of the third part is not what the opening chapters expected. The book's agent team has no response agent: containment is a playbook run by the orchestration layer, with the investigation agent proposing and a named person or a codified rule authorising (Chapters 10 and 13). Autonomy is matched to reversibility in the playbook, and the playbook has an owner. That is a stronger design than a response agent with a ceiling, because the authority is written down in a record that can be reviewed.
The twelve questions
The chapters took up twelve questions. The table gives each an answer, a partial answer or an honest "open", with the chapter that carries it. An answer in the table is the book's conclusion, drawn here.
| Question | Status | The book's answer |
|---|---|---|
| 1. Which functions may be delegated, to what degree, and who decides? | Answered | Per function and action class, by a named authority, recorded in a delegation profile and an AI Decision Record, with a review date and stop numbers (Chapters 4, 10, 13) |
| 2. Who is accountable for a missed intrusion that AI closed? | Answered | The class owner, then the reviewer (only if the process allowed real review), then whoever granted the level, then whoever designed the process; the oversight record makes the chain visible (Chapters 13, 14, 25) |
| 3. Where do the next analysts come from? | Answered in part | Designed routes exist (Chapter 23); their results are not yet known |
| 4. How can an analyst verify what AI concludes from evidence an adversary can write? | Answered in part | Independent reproduction, seeds, controls outside the model (Chapters 14, 15); full reproduction does not scale |
| 5. Which operating model fits when providers embed AI? | Answered in part | No model is the answer; every model must keep decision rights and records and make the provider's AI visible by contract (Chapter 16) |
| 6. Who may isolate, disable or disclose, and how fast? | Answered | Assigned in advance by action class and level, with deputies and times (Chapter 18) |
| 7. How is a blue team measured? | Answered in part | Speed together with coverage, judgement and learning (Chapter 20); resistance to gaming over years is untested |
| 8. How does co-determination apply to monitoring analysts? | Answered in part | Aggregate-only measures agreed first (Chapters 12, 14, 19, 21); national law differs and some cases are unsettled |
| 9. Does AI reduce or intensify fatigue? | Open | It depends on team design; the effect is not yet well measured (Chapter 21) |
| 10. Will there be a SOC in 2036? | Answered in part | The function persists; its form is open (below and Chapter 24) |
| 11. How do sovereignty and cross-border telemetry shape where AI runs? | Answered in part | Route by classification; restricted data to routes the organisation controls (Chapters 12, 16) |
| 12. Which functions should a person, a system or a person conducting systems perform in 2036? | The author's projection | Given in the next section, labelled |
The questions that the book answers most firmly are those that a team can settle by its own decision, the first, second and sixth. Delegation, decision rights and the chain of accountability are choices, and they can be written down before the crisis. The questions answered only in part depend on facts that no single organisation controls: what providers will agree to, what the law allows in a given member state, and whether local models will be good enough for restricted alert data (a design choice today; the quality of local models is an expected trend, not a fact). The one question left open, fatigue, is open because the evidence does not yet exist. A reader who is told that AI will lighten the load, or that it will crush the night shift, is being told something that the studies do not yet show. The honest course for a lead is to measure the load of their own team each quarter, as Chapter 21 describes. The second answer is a statement about organisational accountability and what the records can show, not about legal liability, which differs between member states and is outside the book's scope.
The author's projection for 2036
The twelfth question asks which blue team functions a person, a system, or a person conducting systems should perform in 2036. The third term is Shift 4 of The Transformed Security Architect applied to the analyst: the person who conducts an AI team under a written mandate and remains the accountable verifier of what it produces (66, Nordqvist, 2026). What follows is the author's own projection, one of the two the book allows itself, and not a finding of the book. Following the series' discipline, each element carries a label from AI Governance, Chapter 22 (62, Nordqvist, 2026): observable if it is happening now and documented, expected if a stated trend or a decided instrument supports it, speculation if it is plausible but unsupported by present evidence. The table separates the design rule, what should hold, from the forecast, what is expected to be the practice.
| Function | A person alone (design rule) | A system | A person conducting systems | Label of the forecast |
|---|---|---|---|---|
| B1 Anticipate | Decides what is shared outside and what a hypothesis is worth | Reads, extracts, correlates, drafts hypotheses | Ranks hypotheses, verifies extraction | Expected |
| B2 Detect | Accepts the cost of a false negative | Runs detections; deploys narrow classes after a passing test | Engineers detections and tests; owns coverage | Expected |
| B3 Investigate | Concludes about named people; signs outward narratives | Triages and closes defined low-risk classes; collects evidence | Investigates novel cases; verifies; owns closure classes | Expected |
| B4 Respond | Contains anything wide, irreversible or person-related; discloses; commands | Executes reversible containment inside a playbook | Writes and tests playbooks; holds the stop | Expected |
| B5 Learn | Chooses what changes and what is accepted | Assembles evidence packs, runs re-tests | Runs reviews and exercises; closes findings on a passing re-test | Expected |
The sentence that carries the projection is this. By 2036 the system is expected to read, correlate, draft and execute inside playbooks; the person conducting systems engineers, verifies and learns; and a person alone decides and answers for what cannot be undone, for what is disclosed and for what is decided about people. The projection rests on three grounds, and they support different parts of it. The first is the pace of what is observable: AI already enriches, correlates and closes defined low-risk classes in security tooling, and the book's chapters show it. The second is the instruments already decided: NIS 2 Article 20 and DORA Article 5 fix accountability on the management body (3, European Union, 2022) (2, European Union, 2022). They do not say who performs a function, so this ground supports only the accountability that the table assigns to people. The third is the series' design rule that autonomy is matched to reversibility, and the allocation of functions rests on that rule. Together they make the allocation expected, as a forecast about practice; as a rule about design it is what the book recommends whatever the forecast.
Three things in the projection are speculative, and the author says so. The first is the form of the function. Whether the unit that does this work in 2036 is called a SOC, is a team inside a platform organisation or is a service bought from a provider is open; Chapter 24 sets out the scenarios. The second is the pace: a nine-year horizon in a field where the capability of AI systems has changed visibly within a year cannot be forecast with confidence, and assessments such as the International AI Safety Report 2026 are where a change would show first (38, Bengio et al., 2026). The third is the entry route. That the profession keeps routes into the craft that do not rely on tier-1 triage is something the author recommends and cannot promise.
Worked example: The author's horizon statement
The statement records the projection in the format that Chapter 24 uses for a horizon register. The format is illustrative; the content is the author's own projection, written in November 2026 and reviewed each November, next on 2027-11-10.
# horizon/author-statement-2036.yaml  (illustrative format; the author's projection)
statement: HZN-BT-AUTHOR-2036
version: 1.0.0
written: 2026-11-10
review_date: 2027-11-10
reviewer_role: author-with-two-external-readers
claims:
  - id: H1
    claim: Defined low-risk alert classes are closed by systems under named class owners.
    label: expected
    basis: closure of low-risk classes is observable now (Chapter 7)
    revise_if: published audits show escape rates above the class stop number
  - id: H2
    claim: Detection engineering, novel investigation and learning are done by people conducting systems.
    label: expected
    basis: tested drafts, seeded review and re-tests (Chapters 6, 8, 11)
    revise_if: machine-checkable reasoning removes the need for independent reproduction
  - id: H3
    claim: Wide, irreversible and person-related actions, and disclosure, stay with named people.
    label: expected
    basis: the Level 4 rule; accountability on the management body in NIS 2 Article 20 and DORA Article 5
    revise_if: law or audited multi-year evidence changes the allocation
  - id: H4
    claim: The unit that does this work is still organised as a tiered SOC.
    label: speculation
    revise_if: published staffing data show tiered SOCs below half of surveyed teams (Chapter 24)
  - id: H5
    claim: A fully autonomous detection and response service outperforms a supervised team over years.
    label: speculation
    revise_if: audited escape-rate, recovery and harm data over at least three years
  - id: H6
    claim: Entry routes exist that do not depend on tier-1 triage.
    label: speculation
    risk: the entry rung is lost if no route is designed (Chapter 23)
What would change the view
A thesis that cannot be shown wrong is a slogan. Chapter 1 set one refutation for each part. The table repeats them and adds the further evidence this chapter would weigh, the measure that would reveal it, and what the author would do.
| Claim | Refutation set in Chapter 1 | Further evidence, measured by | Then |
|---|---|---|---|
| Transformed, not abolished | Fully autonomous detection and response, with no human able to verify and stop it, produces better outcomes over years than a team with those properties | Escape rate on seeded and retrospective cases, time to recover, harm | Withdraw the thesis and the Level 4 rule for that class |
| Queue to loop | Queue-centred teams match loop-centred teams on coverage and time to contain, with no more strain on staff | Loop teams showing no fall in load or in missed intrusions over several quarters; detection debt | Revise the second part; keep the records |
| Autonomy and the stop path | Irreversible containment at Level 4 Autonomous causes less harm than the same actions at Level 3 Bounded or below | A Level 3 class with a stable, very low reversal rate across years, or a stop path outside the system that failed when needed; reversals, drill times | Widen the class, or tighten and redesign the stop |
| Defenders' AI in the estate | Agents reading attacker-writable input need no more containment than other automation, over a long exposure | Red-team findings, incident reports | Reduce or increase the weight of the controls |
| Route and wellbeing | AI-handled triage leaves the capacity to investigate novel intrusions intact without people who practise, or wellbeing is unaffected | An AI tutor that produces investigators of equal strength; seeded novel cases, unassisted exercises, competence records | Retire part of the craft programme |
The first refutation is the one that matters most for the projection, and it is a high bar on purpose: the book does not claim that people are better than machines at detecting intrusions. It claims that a team which can verify and stop its AI is safer to depend on than one which cannot, and the evidence that would refute the claim is evidence about outcomes over years, with the property of verification removed. The last is the calm side's best case from the debates of Chapters 7 and 23: if the juniors of 2030 learn faster with an AI tutor and are given real investigation work earlier, then the old tier 1 was a poor school, and the craft programme can be lighter than this book recommends. The book does not rule that out. It argues that a team should not bet its ability to supervise its own AI on a result that nobody has yet shown.
What to do on Monday
A conclusion that leaves the reader with nothing to do has failed. The five roles below are those that Chapter 1 named as readers, and each action is small enough to start in a week.
The analyst
Take the last five alerts that AI closed, and for one of them go back to the raw evidence and form your own view before reading the summary. Record whether the closure stood and whether you checked the fact on which it rested. Ask which closure class you own, or who does, and where the sample is kept. Keep a share of your own cases unassisted (one in five is the default in Chapter 12; the Region's acceptable-use sheet sets one in ten), and say aloud when an approval you were asked to give arrived faster than you could read it. An approval in seconds is a signal about the system, and it is yours to report.
The SOC lead
Write the delegation profile on one page: for each function, the highest level for each action class, the owner of each Level 3 class, the stop holder and the review date. Run one stop drill this month and write down the time. Set the cap on open proposals per reviewer (Chapter 14 uses 12, and 8 at night), start seeding five incidents a month, and agree with the team and its representatives which oversight measures are reported. Protect time for engineering. Do not extend a Level 3 class until the class's own sample and seeded incidents meet the threshold you have written (0.85 is the default of Chapter 27) and the review-quality measure stands at its threshold, and freeze it below 0.80 (Chapter 14).
The CISO
Inventory every AI that takes part in the team's work, including the provider's AI that acts on the organisation's behalf at an autonomy that nobody decided. Obtain the facts by contract and by sample: the classes the provider's AI closes, the evidence it needs, the notice of a model change and the right to stop it. Name the person who may stop each agent and the person who may restart it, and put the time of the last drill in front of the management body. Take the final test of this chapter before the next board meeting. And decide what to stop: one metric that rewards closing alerts faster than catching intrusions, one detection that nobody owns, or one delegation with no review date.
The board member
The management body has duties under NIS 2 Article 20 and DORA Article 5 to approve and oversee the measures, and no tool can discharge them (3, European Union, 2022) (2, European Union, 2022). Three questions put those duties into practice. Who decided what our AI may close or contain, and where is the record? Who can stop it, how long did the last drill take, and can that person act without asking anyone who depends on the system? Could the team run the queue for a week by hand, and when was that last shown? Ask for the answers on one page, and ask what the page does not show. A board that hears only that response times fell has been told about speed, the measure that closing alerts improves most easily.
The employee representative
Ask for the list of tools in the SOC that record what analysts query, decide and approve, including the log of AI use, and ask what each is for. Agree before the tools are used that measures are reported in aggregate, that no measure by person enters an appraisal, and that the purpose and the retention are written down. The legal basis differs by country, so the agreement must be read against national law, including co-determination rights in Germany and the duty to negotiate important changes in Sweden. Ask also for what protects the people: a cap on review volume, a limit on night shifts, protected time for unassisted work, and a stop right that is never treated as a failure when used in good faith. Representatives help most by taking part in the design of the oversight metrics, not only by consenting to them afterwards.
Practical guide: A one-page plan for the first ninety days
Purpose. Move a team from not knowing what its AI does to being able to show, from its own records, who decided what and whether it can stop and recover, within ninety days.
Roles. The SOC lead or lead analyst as owner; the CISO as sponsor; a detection engineer; the privacy officer; an employee representative, involved from day 1.
- Days 1 to 10. Inventory every AI capability that touches the five functions, by mode and level, including the provider's. Mark each as known, observed or assumed. Open one AI Decision Record that commissions the plan.
- Days 11 to 30. Write the delegation profile on one page. Put each closure class, playbook and mandate into version control with a review date. Begin weekly sampling of the provider's closures.
- Days 31 to 60. Run a stop drill and one degraded-mode drill and record the times. Start seeded incidents, the unassisted share and the cap on open proposals. Agree with the representatives the measures to be reported, in aggregate.
- Days 61 to 80. Take the final test below. Write down what the records could not show, and open a finding for each gap, with an owner and a re-test.
- Days 81 to 90. Report on one page to the management body: what the team delegated, to whom, with what record, the drill times, the seeded catch rate, what it stopped doing, and the one change it asks for. Decide on the next delegation only if the numbers allow it.
Definition of done. The one-page profile exists in the repository, the stop time and the degraded-mode time are recorded, the seeded catch rate is known, the measures about people are agreed with representatives, and the management body has read the page and answered the three questions. Defaults, such as one in five unassisted and five seeds a month, are starting points; adapt them to the contract, the works agreement and the size of the team, and write the adapted value down.
The series' argument
The series has made one argument across its volumes, from Architecture as Code, which made decisions and evidence into code that can be reviewed (61, Nordqvist, 2025), to AI Boss, which added a sixth commitment, that a named person sits in the chair for every consequence (67, Nordqvist, 2026). AI Threat distilled the first five into clauses and held that the quiet harms at the scales of the mind and the organisation deserve attention first (65, Nordqvist, 2026). This book applies all six to the team that defends.
| Commitment | What it means for the blue team | Where the book makes it concrete |
|---|---|---|
| Keep decisions as records that can be corrected | Detection, case, playbook, hunt, mandate and review records, and AI Decision Records, in version control | Chapters 6 to 11, 13 |
| Keep the ability to stop outside the system being stopped | A stop path at the identity provider and the orchestration connector, held by named people and drilled | Chapters 10, 13, 15 |
| Keep people able to do the work and judge the output | Unassisted share, seeded incidents, rotation, apprenticeship, oversight-quality measures | Chapters 12, 14, 23 |
| Keep dependence reversible | Contract annexes, exit plans and degraded-mode drills for the provider's AI and the platform | Chapters 15, 16 |
| Match autonomy to reversibility | Action classes, ceilings by lowest answer, Level 3 by playbook, Level 4 never for the irreversible | Chapters 4, 10 |
| Keep a named person in the chair for every consequence | An incident commander, class owners, a named discloser, and never Level 4 for a decision about a named person's access to work | Chapters 10, 18, 21 |
The sixth commitment applies twice in a blue team, and the second application is the one a SOC is least likely to see. It applies to the incidents the team handles: someone named isolates, discloses and answers. And it applies to the analysts themselves. The tools that record an analyst's queries, rank their closures and score their review speed make decisions that shape a named person's work, and AI Boss concluded that management functions that carry consequences for a person have a named human decider, who can be identified, contested and held to account (67, Nordqvist, 2026). A blue team that follows the rule for its incidents and ignores it for its own people has not understood the argument.
If the series has a single sentence for the blue team, it is that AI can take a very large share of the work, and the team must stay able to say who decided, stop what it has started and do the work without it. These are the properties that separate a defence from a dependence.
Limits of this book
This book did not examine, and the reader should not infer from it, the following.
- Outcomes over time. It has no longitudinal data from real SOCs on escape rates, retention, headcount or cost. Its worked cases are illustrative, and the year of Chapter 26 is fiction built from the chapters.
- Costs and economics. It does not weigh the cost of an agent team, of a managed service or of a craft programme against the risk they reduce.
- Evidence quality. Several of its sources on the work of SOCs are qualitative studies, practitioner surveys and agency statements, not controlled trials, and some vendor claims could not be checked.
- Scope of the team. It treats the SOC, detection engineering, intelligence, hunting and incident response. It does not treat operational technology, small organisations without a SOC, or the tradecraft of red and purple teams beyond what a blue team needs to design detections and tests.
- Law in motion. It frames the instruments as architectural implications, not legal advice. The AI Act and other instruments are being amended in parts, and national transposition differs. Each reader must check the live text for their own member state.
- A moving capability. The conclusions rest on the capabilities of AI systems in 2026. A step change would reopen them, and the horizon statement above is where the author will say so.
The final test
The two organisations of the book receive one final test, and so does any reader. It has two questions. Can the team show, from its own records, who or what decided what? And can it stop what it has started, and recover? Both are tests of records and drills, not of opinions. The ceilings of Chapters 4, 10 and 13 are what the test looks at first.
Across the degrees of delegation
| Function | Highest level the book recommends today | At or below Level 2 | Level 4 Autonomous |
|---|---|---|---|
| B1 Anticipate | Level 1 Assisted for extraction and drafting; Level 3 expected for narrow conversions | Any change to detection content | Not used |
| B2 Detect | Level 1 for drafting; Level 2 for branch-only agents; Level 3 for defined closure classes with sampling | Merging a detection without a passing test and a named approver | Not used for detection content |
| B3 Investigate | Level 3 for evidence collection from defined sources and for closure of defined low-risk classes | Conclusions about novel cases; anything about named people | Not used |
| B4 Respond | Level 3 for preservation and narrow reversible actions inside a playbook | Wide, business-critical and person-related actions | Never for an irreversible action or a decision about a named person's access to work |
| B5 Learn | Level 1 or 2 for proposals; the re-test closes a finding | Choosing what changes | Not used |
Nordvik Region and Hansa Mutual
Both organisations take the final test in December 2027, and both record it: Nordvik Region as AIDR-0737 and Hansa Mutual as AIDR-0794. The results are illustrative.
# reviews/final-test-2027.yaml  (illustrative)
final_test:
  - decision_record: AIDR-0737
    organisation: Nordvik Region
    dated: 2027-12-15
    reviewers: [hr-lead, ai-architect, data-protection-officer]
    review_by: 2028-12-15
    tests:
      - question: Who decided what the provider's AI may close?
        method: Trace CASE-NR-0231 to class, owner, sample and reopening.
        result: partly
        note: Sampling (AIDR-0712) and reopening are ours; the provider's rule is not in our records until annex MS-2 is signed.
        next: Obtain the class list under MS-2; owner Karin Lund.
      - question: Can we stop the provider's AI closing alerts out of hours?
        method: Ask the provider to suspend AI closure for one night and time it.
        result: not_yet_shown
        target_minutes: 15          # annex MS-2 stop budget
        next: Run the test with the duty analyst; owner CISO.
  - decision_record: AIDR-0794
    organisation: Hansa Mutual
    dated: 2027-12-15
    reviewers: [chief-risk-officer, head-of-detection-engineering, ai-governance-board-chair]
    review_by: 2028-12-15
    tests:
      - question: Who or what decided each action in INC-HM-2027-0455?
        method: Rebuild from CASE-HM-0455 and PIR-HM-0455.
        result: yes
        note: Each action maps to a playbook or a named role; the 38-second approval was read as a signal and the shift lead reversed it.
      - question: Can we stop the agents and recover?
        method: Compare the stop of the night (57 s) and the re-tested drill (106 s, 2027-06-03) with the 120 s target; compare the degraded-mode drill (14 min 20 s, 2027-06-22) with 15 min.
        result: yes_with_open_item
        note: The stop and the manual queue are verified. Open item - independent reproduction of Level 2 proposals was 0.71 against 0.80 in 2027-Q3 (OQM-HM-SOC-01).
        next: Bring reproduction to 0.80 as the second condition of gate H1; owner SOC lead.
Nordvik Region's result is honest and typical of a hybrid team. It can show its own decisions, because the Region owns the sample, the reopening and the isolation policy in its own endpoint console, but it cannot yet show the provider's, because its framework agreement said nothing about autonomy until annex MS-2 is signed. Its leverage is the contract, and its next step is a test of the provider's stop right against the 15-minute budget. Hansa Mutual can reconstruct the night of INC-HM-2027-0455 action by action, which is the benefit of records built into the playbook, and it has verified its stop and its manual queue by timed drills that first failed and were re-tested. Its gap is the one the oversight report found: reviewers reproduce too few Level 2 proposals independently. Both show the thesis in its two most testable parts, the record and the stop.
Summary
This chapter tested the five-part thesis of the book against Chapters 1 to 27 and found that it held with qualifications in three parts, held in part in one and was argued but not proved in one. The blue team is transformed, not abolished: in every function a person keeps a judgement that must be verified and answered for. The defenders' AI is part of the defended estate, by an architectural argument. Autonomy matched to reversibility, with a stop path outside the system it stops, is the best supported as a design rule, but the book's own illustrative cases found defects in how it was first implemented, and each needed a re-test. The move from the queue to the loop held in part, because the queue remains and a loop with no cap becomes a queue. The route by which analysts are made and their wellbeing held least: it is argued but not proved, a requirement on design and not a result. The functions concerned throughout were B1 Anticipate, B2 Detect, B3 Investigate, B4 Respond and B5 Learn.
The chapter answered the twelve questions: three outright, seven in part, one left open and one, the question about 2036, answered as the author's labelled projection. By 2036 the system is expected to read, correlate, draft and execute inside playbooks (expected); the person conducting systems is expected to engineer, verify and learn; and a person alone is expected to decide and answer for what cannot be undone, what is disclosed and what is decided about people. The form of the organisation, the pace and the entry route into the profession are speculation. The chapter listed the evidence that would change each part, and the first and highest bar is multi-year outcome evidence that a team without a human able to verify and stop its AI does better.
On Monday an analyst can read one closure back to the raw evidence, a SOC lead can write a one-page delegation profile and run a stop drill, a CISO can inventory the AI that acts in the team's name, a board member can ask who can stop it and how long it took, and an employee representative can ask what is recorded about the analysts and agree the limits first. The ninety-day plan joins these into one routine. The series' argument closes with the blue team: keep decisions as records that can be corrected, keep the ability to stop outside the system being stopped, keep people able to do the work and judge the output, keep dependence reversible, match autonomy to reversibility, and keep a named person in the chair for every consequence. The glossary collects the vocabulary of the book, and Appendix A gives the artefacts in full.
Sources
- Nordqvist, G. (2025). Architecture as Code. The Architecture as Code Series, Book 1. (61, Nordqvist, 2025)
- Nordqvist, G. (2026). AI Governance: Governing Artificial Intelligence in European Enterprises and Public Authorities. The Architecture as Code Series, Book 2. (62, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Platform and Security: Building and Securing AI Platforms in European Enterprises and Public Authorities. The Architecture as Code Series, Book 3. (63, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Red Team: AI as an Active Part of Cyber Defence in European Enterprises and Public Authorities. The Architecture as Code Series, Book 4. (64, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Threat: Are the Dystopias Coming True? Evidence, Risk and Response for European Enterprises and Public Authorities. The Architecture as Code Series, Book 5. (65, Nordqvist, 2026)
- Nordqvist, G. (2026). The Transformed Security Architect: Role, Craft and Career in the Age of AI in European Enterprises and Public Authorities. The Architecture as Code Series, Book 6. (66, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Boss: When Artificial Intelligence Manages People in European Enterprises and Public Authorities. The Architecture as Code Series, Book 7. (67, Nordqvist, 2026)
- European Parliament and Council of the European Union. Regulation (EU) 2022/2554 on digital operational resilience for the financial sector (DORA). Official Journal of the European Union, 27 December 2022. (2, European Union, 2022)
- European Parliament and Council of the European Union. Directive (EU) 2022/2555 on measures for a high common level of cybersecurity across the Union (NIS 2 Directive). Official Journal of the European Union, 27 December 2022. (3, European Union, 2022)
- Bengio, Y. et al. (2026). International AI Safety Report 2026. International AI Safety Report, 3 February 2026. (38, Bengio et al., 2026)
- Alahmadi, B. A., Axon, L. & Martinovic, I. (2022). 99% False Positives: A Qualitative Study of SOC Analysts' Perspectives on Security Alarms. 31st USENIX Security Symposium. (69, Alahmadi et al., 2022)
- Tariq, S., Baruwal Chhetri, M., Nepal, S. & Paris, C. (2025). Alert Fatigue in Security Operations Centres: Research Challenges and Opportunities. ACM Computing Surveys 57(9). (72, Tariq et al., 2025)
- Bainbridge, L. (1983). Ironies of Automation. Automatica 19(6). (75, Bainbridge, 1983)
- Parasuraman, R. & Manzey, D. H. (2010). Complacency and Bias in Human Use of Automation: An Attentional Integration. Human Factors 52(3). (76, Parasuraman & Manzey, 2010)