Triage Transformed: From Alert Queue to Verified Case
Triage is the work that defined tier 1 of the security operations centre (SOC): deciding whether an alert is real, how bad it is and who needs to know. This chapter takes as its premise, argued in Chapter 3, that AI can now take part in that work: it enriches, correlates, summarises and, where an organisation or a supplier allows it, closes alerts without a person reading them. It describes triage as transformed and asks the question that follows honestly: what is lost and what is gained when a machine closes the alert, who answers for an intrusion that was closed by mistake, and how the quality of triage is shown when most alerts are never read by a person. It concerns B2 Detect, because the alerts that reach triage are the product of detection and their closure is the measure of its cost, and B3 Investigate, because triage is the first step of investigation and the point where an alert becomes a verified case or is set aside. The chapter takes the capability map of AI Red Team, Chapter 18, as given (64, Nordqvist, 2026) and asks what it does to the work, the record and the people.
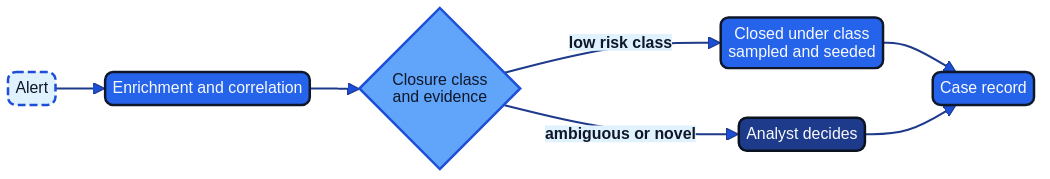
Figure 7.1: The alert-to-case path with closure classes, the evidence needed to close, sampling and the point where a person decides.
The alert as a claim
An alert is a claim about the world: this pattern of events indicates activity that deserves attention. Like any claim it needs evidence, context and a decision, and it can be wrong in two ways. It can be false, because the detection logic fired on something that is not what it describes, or it can be accurate and benign, because the event is real but reflects legitimate behaviour in the organisation. The distinction matters for what AI can be asked to do. In a qualitative study of SOC practitioners, Alahmadi, Axon and Martinovic surveyed 20 practitioners and studied 21 more; they report that most of the alarms practitioners called false positives were in fact benign triggers, technically accurate alarms that reflect legitimate behaviour, and that validating alarms is tedious and can lead to alarm burnout and desensitisation (69, Alahmadi et al., 2022). The study describes what practitioners said, not how many intrusions were missed. It does show where the volume comes from and why closing it is a different problem from finding intrusions: much of the queue is made of true statements about harmless events.
Triage therefore consists of three decisions that are worth keeping apart, because they can be delegated differently. The first is validity: is the claim true, and what does the evidence say? The second is consequence: if it is true, how bad is it, which assets and which people are concerned, and is the activity still going on? The third is routing: who must act, and by when? In the traditional model tier 1 made all three for every alert. Tier 1 was also the entry rung of the profession: analysts learned what normal looks like by closing thousands of alerts that were normal. That second function was never written into a job description, and AI removes it without anyone having decided to. Chapter 23 returns to it.
The central question of the chapter is therefore not whether a machine is faster at triage, which it is assumed to be. The question is what an organisation must have in place before a machine is allowed to close an alert, so that closure is a decision somebody made in advance, can be measured, and can be withdrawn.
What AI does in triage
AI takes part in triage in five tasks, each with its own value and its own failure mode. The tasks differ in how much they change the evidence a person sees, and that difference, rather than the brand of the tool, sets the control each needs.
| Task | What the AI system does | Characteristic failure |
|---|---|---|
| Enrichment | Retrieves context: asset owner, recent changes, threat intelligence, previous alerts for the same entity | Stale or wrong context presented with the same confidence as correct context |
| Correlation | Links the alert to related alerts and events across sources | Over-linking that builds a story, or under-linking that splits one intrusion into many cases |
| Deduplication | Folds repeated alerts into one case | Folding a new event into an old, benign case |
| Summarisation | Drafts a short account of what happened and why it matters | A fluent summary that is not grounded in the evidence, or that carries text the adversary wrote |
| Closure | Closes the alert under a stated class, or recommends closure | Closing a class that sometimes hides an intrusion |
Enrichment and deduplication are the least controversial and the most valuable: they gather the same six facts the analyst would gather for the fortieth time. Their risk is quiet. An enrichment that attaches the wrong asset owner does not look like an error, and a deduplication that folds a new event into an open case removes the new event from view. Both are tested by comparing output with source records on a sample.
Summarisation is the task people notice, and the one where the hazard of the whole field is most compact. A summary is a view of the evidence, not evidence. A fluent paragraph is easy to accept, and the research on how people use automated aids gives reason to expect that it will be: Parasuraman and Manzey review complacency and bias in human use of automation (76, Parasuraman & Manzey, 2010), and AI Threat, Chapters 6 and 14, drew the consequence for oversight, namely that reliance on AI reduces checking among those who trust the tool and erodes the skills of those who must catch its errors (65, Nordqvist, 2026). The design response, review that does not start from the AI's answer, independent reproduction, seeded errors and an oversight-quality metric, is set out in Chapter 14 and applies here unchanged.
There is a second hazard in summarisation that is particular to security. Alerts carry fields that other people write: the subject line of a reported email, a file name, a command line. The adversary can influence all of them, and Chapter 8 sets out why the defence lies outside the model. For triage the rule is simple to state. A closure rests on structured fields and on checks that run in a policy point the model cannot influence, never on the narrative the model wrote. The narrative is there for the analyst's convenience; it authorises nothing.
Closure is the task that changes the nature of the work. An AI system that enriches and summarises leaves the decision with a person. Closure is itself a decision, and the open question is whether anyone delegated it. That is the subject of the next section.
The closure policy
A closure policy answers one question in advance: for which classes of alert may an AI system close the alert without a person reading it, on what evidence, and with what check afterwards? The word class carries the argument. An individual alert is never safe to close in general, because one in the class may be the intrusion. A class can be shown to be safe to close in the sense that matters: its members are, over a measured period, overwhelmingly benign, closing them without a person costs little when one is wrong, and the check afterwards would reveal a change.
Each class in the policy has a small set of properties:
- A definition narrow enough to be tested, expressed in structured fields (source, rule, asset class, user group), not in the words of a summary.
- The evidence required to close: the conditions that must all hold, each checkable by the policy point.
- The degree of delegation per class, using the autonomy levels of AI Red Team, Chapter 6: Level 1 Assisted where the system recommends closure and a person confirms, Level 2 Supervised where the system closes and a person reviews a stream, Level 3 Bounded where the system closes inside a codified playbook enforced by a policy decision point outside the model (64, Nordqvist, 2026).
- A named owner, a person, who answers for the class.
- A sampling rate, and a rate of seeded incidents.
- A stop condition, stated as a number, and the identity of the person who may reinstate the class.
Two exclusions belong in every policy. Level 4 Autonomous is not used for closure of any class that can hide an intrusion in progress, and no class is closed by an AI system where the alert concerns a tier-0 asset, a privileged or executive account, or a named person's access to work. The second exclusion follows from the series' rule that no AI system decides about a named person's access to work (AI Boss, Chapter 4) (67, Nordqvist, 2026). Disabling a person's account or suspending their access is such a decision and stays with a named human; temporary isolation of a device or revocation of a session is reversible containment (Chapter 10), not a decision about the person. A triage verdict on a colleague's behaviour is the first step toward the former and is kept with a person.
Who answers when a class closes an intrusion? The earlier volumes settled the principle: every machine identity has an owner, operators and an authority who are named people, and at Level 3 approval moves from the action to the playbook and the decision record, which concentrates accountability rather than diluting it (64, Nordqvist, 2026). NIS 2 Article 20 and DORA Article 5 make the management body responsible for oversight of risk management and of ICT risk (3, European Union, 2022) (2, European Union, 2022); the book's reading is that neither lets that responsibility pass to a tool.
Applied to triage, this gives a clear division. The class owner answers for the definition of the class and its measured performance. The authority that approved the delegation, the SOC lead with the CISO, answers for the decision to delegate. The analyst who reviews a sample answers for the review, and only if the review was real. The corollary, which is the book's own conclusion, is uncomfortable for Level 2: an analyst who confirms closures in seconds, without the evidence in front of them, has not taken responsibility for the closure and has made it harder to say who did. A class is better placed honestly at Level 3 with a named owner and a measured escape rate than nominally at Level 2 with approvals that nobody reads (AI Governance, Chapters 10 and 21) (62, Nordqvist, 2026).
Practical guide: Writing a closure policy for three alert classes
Purpose. Produce a first closure policy that delegates three alert classes and can be stopped.
Roles. The SOC lead (approves), a senior analyst or investigation lead as class owner for each class, a detection engineer (provides the structured fields and tests), the CISO (approves the delegation), and, where the analysts' work is measured by tools, the employee representatives (agree how sample results are reported).
- Pull 90 days of closed alerts and group them by rule and asset class. List the ten largest groups by volume.
- Choose three candidate classes that are high in volume, narrow in definition and low in consequence when wrong. Good first candidates are traffic from a registered internal vulnerability scanner, a duplicate of an alert already in an open case, and the alerts of a documented, registered automation such as a backup or patch job inside its scheduled window. Poor candidates are anything touching identity, remote access or privileged accounts. Reported phishing is a tempting first class and a poor one:
CASE-NR-0231below was a reported phishing lure closed on sender reputation. The class is safe only if the evidence to close includes the click log, as SC-03 in the policy below requires; without it, it is the failure case. - Write the definition and the evidence to close in structured fields. For each condition, name the data source and the check that confirms it.
- Measure the class by hand first. Have two analysts independently review a random sample of 100 historical alerts per class. A class in which either analyst finds a true positive is not ready.
- Set the starting level at Level 1 Assisted for four weeks, so that the AI system's recommended closures are compared with analysts' decisions before it closes anything. Move a class to Level 3 Bounded only when agreement is stable and the class owner signs.
- Set sampling and seeding. As defaults, review 5 per cent of closures in each class, with a floor of 20 a month, and seed at least five known incidents per class per quarter. Raise both for a class that has just moved up a level, and adapt them to volume and to the works agreement.
- Write the stop condition as numbers, and make it stop closure. Any one confirmed escape of high severity or one missed seeded incident returns the class to Level 1 Assisted at once: the system recommends and a person closes, so nothing is closed unread. With five seeds per class per quarter, one miss is a catch rate of 0.80, the threshold of the review protocol (Chapter 14); the stop acts on the first miss because the class is closing without a person. A lesser trigger, two confirmed escapes of lower severity in 30 days, steps the class down one level. Give the duty manager the right to disable a class at the policy point without asking anyone.
- Record the decision as an AI Decision Record, link it to the delegation profile, and set a review date no more than six months ahead.
Definition of done. Each class has a definition in structured fields, a named owner, a starting level, a sampling rate, a seeding plan, a stop condition with numbers, and a review date; the policy point enforces it; the duty manager can disable a class; and the employee representatives have agreed how sample results are reported.
Worked example: Closure policy and a case record
Illustrative. The first artefact is the closure policy of Hansa Mutual's group SOC, in triage/closure-policy.yaml. It is enforced by the SOAR policy point, not by the model, and it is read by the triage agent as a ceiling.
policy: CLOSE-HM-SOC
version: 1.2.0
decision_record: AIDR-0765
mandate: MND-HM-SOC-01
delegation_profile: DLG-HM-SOC-01
enforced_by: soar-policy-point
review_date: 2027-09-30
never_closed_by_agent:
  - asset_tier: tier-0
  - account_group: executive
  - touches_person_access_to_work: true
  - severity_at_or_above: high
classes:
  SC-01:
    name: Registered vulnerability scanner traffic
    level: Level 3 Bounded
    owner: investigation-lead-network
    close_when:
      - source_in_scanner_register
      - scan_window_open
      - no_follow_on_activity_from_source_24h
    sampling_rate: 0.05
  SC-02:
    name: Duplicate of an open case
    level: Level 3 Bounded
    owner: investigation-lead-cases
    close_when:
      - same_entity_and_rule_as_open_case
      - no_new_field_values_vs_open_case
    sampling_rate: 0.05
  SC-03:
    name: Reported phishing, quarantined, no click
    level: Level 2 Supervised
    owner: investigation-lead-mail
    close_when:
      - quarantined_before_delivery_to_others
      - no_click_recorded
      - sender_domain_blocked
    sampling_rate: 0.10
seeding:
  incidents_per_class_per_quarter: 5
  register_visible_to_analysts: false
reporting:
  results_by_analyst: never
  level: team
stop_condition:
  suspend_closure_and_revert_to: Level 1 Assisted    # the agent recommends; a person closes
  any_of:
    - confirmed_escape_severity: high
    - seeded_incident_missed: 1
  step_down_one_level_if:
    - confirmed_escapes_rolling_30_days: 2
  reinstated_by: class_owner_with_soc_lead
  disabled_by: duty_manager_at_policy_point
The second artefact is a case record from Nordvik Region, the verified account of an alert that the provider's AI closed and an analyst reopened on sampling. The Region had adopted a weekly sample of the provider's closed alerts (AIDR-0712) before the case, and the sample is what caught it. The provider's AI sits outside the policy above because Nordvik has no closure policy for it yet; the record shows what that costs.
case: CASE-NR-0231
organisation: Nordvik Region
status: closed-after-reopen
alert_source: email-security gateway, user report
technique: T1566.002   # ATT&CK: Phishing, spearphishing link
steps:
  - at: "2027-03-06T02:09:00+01:00"
    actor: gateway phishing-report classifier (Mode 0, vendor)
    conclusion: classed as low-risk bulk mail
    basis: sender reputation score
    delegated_by: none recorded
  - at: "2027-03-06T02:14:00+01:00"
    actor: provider triage AI (Mode 0, version not disclosed)
    conclusion: alert closed
    basis: classifier output; provider rule not disclosed
    delegated_by: none recorded
  - at: "2027-03-08T08:40:00+01:00"
    actor: senior security analyst
    action: reopened by the weekly sample of provider-closed alerts (AIDR-0712)
    evidence: message headers, link target, gateway click log
    conclusion: credential-harvesting lure addressed to a benefits-unit group
  - at: "2027-03-08T09:25:00+01:00"
    actor: senior security analyst
    action: sessions revoked and password reset for one recipient
    evidence: gateway click log shows one click on 2027-03-06
    conclusion: no use of the credentials found in sign-in logs
    reviewed_by: CISO deputy
closure:
  closed_by: senior security analyst
  closed: "2027-03-08T11:10:00+01:00"
  significant_incident: false
lessons:
  - decision_record: AIDR-0712   # weekly sample, in force before the case; it worked
  - decision_record: AIDR-0722   # requirement set carried into annex MS-2
  - contract: class list, evidence to close and sampling terms in annex MS-2
Measuring triage quality
Closure speed is the measure that comes free, and it is the wrong one. A queue can be cleared faster by closing more alerts, and time to detect and time to respond, the programme measures of Architecture as Code (Chapter 9B) (61, Nordqvist, 2025), can both improve while the quality of judgement falls. That is the question of how a blue team is measured when its speed can be bought by closing, and Chapter 20 treats it in full. For triage the answer begins with four measures that speed cannot buy.
Escape rate by class. The share of closed alerts in a class that a later review shows should not have been closed. It is estimated from the sample. The estimate has limits that the team should state: if 600 closures are sampled and none escapes, the 95 per cent upper bound on the class's escape rate is roughly 0.5 per cent (the rule of three: about three divided by the sample size). That is a statement about the class as a whole. It says little about whether the one intrusion in a year was in the class, which is why the next measure exists.
The arithmetic also constrains the default sampling rate. At 5 per cent with a floor of 20 a month, a class with 400 closures a month yields 20 samples a month, an upper bound of about 15 per cent after the first month and 0.5 per cent only after 30 months. The class owner has three options: raise the rate for the first quarter, accept low precision and lean on the seeds, or keep the class at Level 2 until the sample is large enough.
Seeded-incident catch rate. A seeded incident is a known case injected into the stream so that review can be seen to catch it. Seeds are synthetic or replayed alerts, ideally drawn from the purple exercises of Chapter 11, and they test the whole path: whether the class definition admits them, whether the AI system closes them, and whether the sample or the analyst reopens them. They test the path against failures the team can imagine and say nothing about the ones it cannot. They carry a duty. Analysts are told that seeding exists, the register is kept away from them, and results are reported for the team, never by name, which in Nordvik Region is also what the union has negotiated for closure rates.
Retrospective audit. When an intrusion is found by other means, a hunt, an incident or a purple exercise, the team traces backwards: did any alert in the stream point at it, and was it closed? Each such trace is the most informative evidence the team will get about escape, because it comes from a real case. A closed alert that pointed at an intrusion is a finding for the class, the detection and the policy, and it enters the learning loop of Chapter 11.
Reopen rate and the oversight-quality metric. The share of closures an analyst reopens on review is a signal in both directions: too high, and the class is not safe; zero over many months, and the review may not be real. The oversight-quality metric introduced in AI Boss, Chapter 26, makes the second reading explicit: time to approval, rejection rate and reversals, with approvals given in seconds treated as a signal of rubber-stamping, reported in aggregate and agreed with employee representatives first (67, Nordqvist, 2026). Chapter 14 sets out how it is applied to the analyst's review of what an AI system concludes.
None of these measures belongs in an individual's performance review: a ranking of analysts would pull the metric toward whatever the ranking rewards. At Hansa Mutual the SOC annex to the works agreement forbids it; in Nordvik Region the union has negotiated it for closure rates. The same rule is a design choice in its own right: a measure of the system's judgement is useful because analysts have no reason to game it.
The verified case
The output of triage is not a closed alert but a case record, CASE-*: the verified account of what the alert was, with the evidence, the reasoning and a note of who or what reached each conclusion. The last part is what distinguishes this book's case record from a ticket. A ticket says the alert was closed. A case record says that a classifier assigned a score, that a triage agent closed the alert under class SC-02 at a stated level, that a named class owner is answerable for that class, that a sample reviewer did or did not reopen it, and which evidence each step used. When the AI system is vendor-embedded, the record shows what it cannot show: that the delegation is not recorded (the delegated_by: none recorded fields in CASE-NR-0231). A blank in a record is a finding.
A verified case has five properties.
- Provenance of every conclusion, naming the actor (a person, a classifier, an agent identity) and the usage mode in which it acted.
- Evidence by reference, not by quotation: pointers to the logs, headers and objects, so that a reviewer can reproduce the step without the AI system.
- The class and the level under which any closure happened, linked to the decision record that authorised them.
- Timestamps that serve the clock. NIS 2 Article 23 sets an early warning within 24 hours of becoming aware of a significant incident (3, European Union, 2022), so the case must show when the organisation, through a person or a system it had delegated to, became aware. Chapter 19 treats the clocks.
- Reproducibility without the AI. Another analyst can follow the evidence references and reach, or contest, the conclusion. This is the property that lets the team keep its judgement independent of the tool, and it connects to the investigation practice of Chapter 8.
Managed triage
Many organisations do not run their own triage, at least out of hours. A managed security service provider (MSSP), or a managed detection and response (MDR) service, receives the telemetry, triages the alerts and escalates what it judges to need attention. Where the provider puts AI in that path, the series has a name for what this does to the customer: the Mode 0 blind spot. Vendor AI in security products and managed services may already act at an effective autonomy nobody decided, so its use and its autonomy have to be established, recorded and required by contract before they are relied on (AI Red Team, Chapters 8 and 28) (64, Nordqvist, 2026).
For Nordvik Region this is the present condition. The framework agreement NR-2025-044 requires processing and log storage inside the EU and EEA, and annex MS-1 fixes paging times and the Region's ownership of detection content. Neither says anything about autonomy, sampling or notice of model change, and the provider's AI closes a class of low-severity alerts out of hours. The Region can see the alerts that were closed only in the handover list; it cannot see the rule that closed them. CASE-NR-0231 shows what that looks like. A security leader who cannot describe the closure policy of the party that triages their night does not have a closure policy.
The Region's requirement set (AIDR-0722) has six terms: a class list with notice before a class is added; the evidence to close for each class, in fields the customer can check; sampling by the customer of a defined share of closures with the provider's evidence; seeding rights; notice of model change (20 working days) with the provider's own escape findings; and a stop right the customer can exercise outside the provider's platform, so that closure by class ceases and alerts go to a person. Annex MS-2 (Chapter 16) groups the same content into six contract terms with a conditions block.
For a public authority the terms must fit the framework agreement and public-access rules. For a group such as Hansa Mutual they apply to every security AI service, and DORA's third-party risk rules require the dependence to be registered and exit planned (2, European Union, 2022).
The debate
Whether AI should be allowed to close alerts is a question on which sensible practitioners disagree, and the disagreement is worth staging in its strongest forms before it is resolved.
The case for concern
The strongest version of the concern has three parts, each with an identifiable source. The first is about what is lost. Bainbridge's ironies of automation make the point: automating a task does not remove the human role, it leaves the human with the tasks the automation cannot do, and takes away the routine practice that would have kept them able to do those (75, Bainbridge, 1983). Closing alerts was how analysts learned what normal looks like. The second is about what is hidden. Parasuraman and Manzey review complacency and bias in the human use of automation: people who trust an aid check less (76, Parasuraman & Manzey, 2010). A system that closes alerts under a plausible summary can hide an intrusion behind it, and a closed intrusion is not in the queue to be found again.
The third is about accountability. A closure by a tool belongs to no one in particular: the analyst did not read it, the engineer did not write the rule for this case, and the manager approved a policy and not an alert. A methodological point sharpens it. Escape rates are measured on known cases while the dangerous ones are the unknown, so a low measured rate is a statement about the past that cannot cover a novel technique. That is an argument from the structure of the measurement, not a finding.
The case for calm
The strongest sceptical version starts from the present. Human triage at current volumes is already shallow. The practitioners in the study cited earlier described alarm validation as tedious and reported desensitisation (69, Alahmadi et al., 2022), and a survey of research on alert fatigue in SOCs treats the problem as a research challenge in its own right (72, Tariq et al., 2025). The evidence cuts both ways, since desensitisation also describes what happens to the analyst who closes the fortieth identical alert of the day.
The calm argument built on it is an inference, and its supporters can state it as an assertion only. A class definition tested on 90 days of data and checked on a sample applies the same rule every time, which a tired human does not; the people freed from the repetitive classes can work the cases that need them; and sampling is a stronger control than the current process, which has no estimate of its escape rate at all. No source cited here compares escape rates under AI closure with those under human triage. In the book's reading, an organisation that does not close by class closes by neglect, as unread alerts age out of the queue.
Where the positions meet
Both positions accept more than the argument suggests. They agree that closure must be by class and not by alert. They agree that the escape rate must be measured, against seeded incidents and retrospective cases and not only against a sample of the known. They agree that someone named must own each class. They agree that the learning ground is a real cost, and that the answer is a deliberate one. What the positions do not share is a prediction: one expects measurement and stop conditions to be sufficient, the other expects them to be applied less rigorously over time as the queue grows and the sampling feels like overhead. The evidence cited reports what practitioners experience and how people use automated aids, not missed intrusions under AI closure, so neither prediction can be settled from it.
What can be done
- Close by class, with a named owner for each class, a definition in structured fields and the evidence to close stated in advance.
- Sample and seed, with the sampling done by a reviewer who does not start from the AI system's summary, and report escape and catch rates at team level.
- Keep a share of triage unassisted, so that the skill survives and the AI system's output is calibrated. The share is set in the acceptable-use policy of each organisation (Chapter 12): one case in ten at Nordvik Region and one in five at Hansa Mutual.
- Write the stop condition as a number and give the duty manager the right to disable a class at the policy point.
- Review the policy on change: a new model version, a changed detection or a missed seeded incident is a trigger, not a calendar entry.
- Agree the measures with employee representatives first, and report them in aggregate.
- For boards and CISOs: ask for the closure policy by class, the latest escape and catch rates, and who owns each class. Ask the same of the managed provider.
Verdict
The evidence supports a narrow conclusion, and closure is a B3 Investigate matter; B2 Detect is affected through the precision of the detections whose alerts are closed. It is observable, on the practitioner studies cited, that most of the queue is benign triggers and that validating them wears analysts down; it is not observable from any source cited here how often AI closure hides an intrusion. The book makes no forecast of its own about closure (the author's projections are in Chapters 24 and 28) and offers a design position instead: extending closure to medium-risk classes is defensible only where sampling and seeding show low escape rates over time, and the instruments for that, the policy point, the sampling and the stop condition, exist now. Unsupervised closure of all alerts, without a named owner and a stop path outside the system, is speculation, and the argument of this chapter is that it should not be pursued. What organisations and people can influence is the discipline around the closure: the class definitions, the measures, the contract with the provider, the share of triage that stays with people and the willingness to withdraw delegation when a number says so.
What the analyst does now
When the repetitive classes are closed by class, the queue that reaches an analyst is different in kind: the ambiguous alerts, the novel ones, and the high-consequence ones that no policy allows an AI system to close. The analyst's work shifts from clearing to deciding. It has four parts: reviewing closures by reading samples against the evidence and reopening; handling the residual queue, which resembles tier 2 more than tier 1 and is the work of Chapter 8; owning classes, reading escape rates and tuning definitions with the detection engineers; and teaching the system what it did not know, since every reopened closure is a finding that enters the loop of Chapter 11.
A short queue of difficult cases does not make the work easier, and the first rung of the career ladder has been removed. Chapter 21 treats the load on the analyst, and Chapter 23 the apprenticeship problem.
Across the degrees of delegation
| Setting | Mode and level | What it means for triage |
|---|---|---|
| Triage inside a product or a managed service | Mode 0 Ambient AI; effective level undecided | Acts without a recorded decision; establish, record and contract before relying on it |
| Chat assistant used by the analyst | Mode 1 Conversational assistants; Level 0 Advisory | The analyst pastes and reads; nothing is closed by it |
| Embedded assistant in the SIEM console | Mode 2 Embedded workplace assistants; Level 1 Assisted | Summarises and recommends; the analyst closes with the analyst's identity |
| Triage service built in-house | Mode 4 Built AI applications; Level 1 Assisted or Level 2 Supervised | Recommends closure, or closes and is reviewed from a stream |
| Triage agent with its own identity | Mode 5 Autonomous production agents; Level 3 Bounded for defined classes | Closes only classes in the closure policy, enforced by a policy point outside the model |
| Closure of a class that can hide an intrusion in progress | Level 4 Autonomous | Not used |
| Any alert about a named person's access to work | Level 1 Assisted at most | A person closes; device isolation or session revocation is reversible containment, not a decision about the person |
Nordvik Region and Hansa Mutual
Nordvik Region's triage assistant NR-SEC-001 runs at Level 1 Assisted on the Region's reserved capacity, because alert data contains personal and health data (AIDR-0301). It summarises and recommends and closes nothing. The Region's exposure lies elsewhere: the provider's AI closes a class of low-severity alerts out of hours under a contract that says nothing about it, which is the Mode 0 blind spot in its plainest form. The Region had adopted a weekly sample of the provider's closed alerts, reviewed by the senior security analyst, Karin Lund (AIDR-0712), before CASE-NR-0231, and the sample is what reopened it; after the case the Region sent its six-term requirement set (AIDR-0722) to the provider as the basis for annex MS-2. With six analysts and a procurement cycle, the Region's lever is the contract and a modest sample, not a policy point it owns.
Hansa Mutual's group SOC has the platform and the people to do more. Its triage agent, which runs as HM-SEC-006 under MND-HM-SOC-01, closes classes SC-01 and SC-02 at Level 3 Bounded with 5 per cent sampling and a named class owner for each (AIDR-0765), and SC-03 stays at Level 2 Supervised until its sample is stable. The policy sits beside DLG-HM-SOC-01, and the policy point and the duty manager's right to disable a class sit outside the model. Its difficulty is different: the results of sampling are produced by tools that log analysts' reviews, and under BetrVG §87(1) no. 6 the Konzernbetriebsrat co-determines on such tools, so the reporting rules in the policy (team level, never by analyst) had to be agreed before the first sample was drawn. The Polish service centre, with its own employee representatives, applies the same policy; the duty manager of the night shift, who is the shift lead there, holds the right to disable a class.
Summary
This chapter described triage as transformed. An alert is a claim that needs evidence, context and a decision. AI takes part in five triage tasks, enrichment, correlation, deduplication, summarisation and closure, and only closure takes the decision away from a person. Closure is therefore delegated by class, under a policy that states the definition, the evidence to close, the degree of delegation, the owner, the sampling and seeding rates and a stop condition written as numbers, enforced by a policy decision point outside the model.
The quality of triage is shown by measures that speed cannot buy: escape rate by class, seeded-incident catch rate, retrospective audit and the reopen rate, read together with the oversight-quality metric and reported at team level. The output of triage is a case record that names who or what reached each conclusion and under which delegation, so that a blank in the record is visible as a finding. Managed triage with embedded vendor AI is the Mode 0 blind spot in practice, and the answer is a contract that gives the customer the class list, the evidence, sampling, seeding, notice of model change and a stop right.
The debate whether AI should be allowed to close alerts ends in agreement on method and disagreement on prediction. The burden of benign triggers is observable on the studies cited, extension to medium-risk classes is a design position that depends on measures staying low, and unsupervised closure of all alerts is speculation. This chapter concerned B3 Investigate, where closure sits, and B2 Detect, whose precision it measures. What the analyst does now is review closures, work a residual queue, own classes, and feed every reopened closure back into the detections.
Chapter 8 follows the case that survives triage into B3 Investigate proper: hypotheses, timelines and evidence with AI, and the hazards of evidence that the adversary can write.
Sources
- Nordqvist, G. (2025). Architecture as Code. The Architecture as Code Series, Book 1. (61, Nordqvist, 2025)
- Nordqvist, G. (2026). AI Governance: Governing Artificial Intelligence in European Enterprises and Public Authorities. The Architecture as Code Series, Book 2. (62, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Red Team: AI as an Active Part of Cyber Defence in European Enterprises and Public Authorities. The Architecture as Code Series, Book 4. (64, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Threat: Are the Dystopias Coming True? Evidence, Risk and Response for European Enterprises and Public Authorities. The Architecture as Code Series, Book 5. (65, Nordqvist, 2026)
- Nordqvist, G. (2026). The Transformed Security Architect: Role, Craft and Career in the Age of AI in European Enterprises and Public Authorities. The Architecture as Code Series, Book 6. (66, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Boss: When Artificial Intelligence Manages People in European Enterprises and Public Authorities. The Architecture as Code Series, Book 7. (67, Nordqvist, 2026)
- European Parliament and Council of the European Union. Regulation (EU) 2022/2554 on digital operational resilience for the financial sector (DORA). Official Journal of the European Union, 27 December 2022. (2, European Union, 2022)
- European Parliament and Council of the European Union. Directive (EU) 2022/2555 on measures for a high common level of cybersecurity across the Union (NIS 2 Directive). Official Journal of the European Union, 27 December 2022. (3, European Union, 2022)
- Alahmadi, B. A., Axon, L. & Martinovic, I. (2022). 99% False Positives: A Qualitative Study of SOC Analysts' Perspectives on Security Alarms. 31st USENIX Security Symposium. (69, Alahmadi et al., 2022)
- Tariq, S., Baruwal Chhetri, M., Nepal, S. & Paris, C. (2025). Alert Fatigue in Security Operations Centres: Research Challenges and Opportunities. ACM Computing Surveys 57(9). (72, Tariq et al., 2025)
- Bainbridge, L. (1983). Ironies of Automation. Automatica 19(6). (75, Bainbridge, 1983)
- Parasuraman, R. & Manzey, D. H. (2010). Complacency and Bias in Human Use of Automation: An Attentional Integration. Human Factors 52(3). (76, Parasuraman & Manzey, 2010)