Measuring the Transformed Blue Team: Speed, Coverage and Quality of Judgement
This chapter describes how to measure a blue team that works with AI without rewarding the wrong behaviour. The measures most security operations centres (SOCs) report, mean time to detect, mean time to respond, closure rate and alert volume, can all improve while fewer intrusions are caught. The chapter proposes measures of speed, coverage, quality of judgement and learning, each paired with the check that shows when it is being gamed, and it shows how they reach the board on one page. It concerns all five blue team functions: B1 Anticipate, through the coverage that intelligence selects; B2 Detect, through verified detections and the cost of alerts; B3 Investigate, through escape rate and the quality of review; B4 Respond, through time to contain and recoverability; and B5 Learn, through the time from finding to verified control. It answers two questions: how a blue team is measured when time to detect and time to respond can be improved by closing alerts faster, and what measures show the quality of its judgement. It also says how measures about people are agreed.
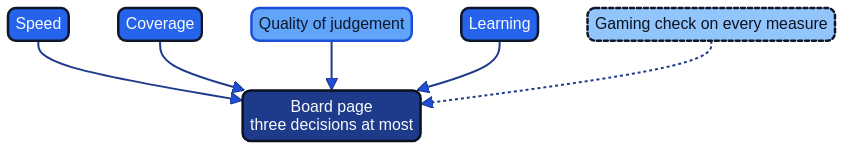
Figure 20.1: Measures arranged by speed, coverage, judgement and learning, with the gaming checks marked.
What the old measures reward
The programme metrics of Architecture as Code (Chapter 9B) are mean time to detect (MTTD), mean time to respond (MTTR) and the false-positive ratio (61, Nordqvist, 2025). They were chosen to push manual response to keep pace with attackers. Mandiant reports a global median dwell time of 14 days for its 2025 investigations, up from 11 days, and reports that organisations first detected malicious activity internally in 52 per cent of cases, up from 43 per cent in 2024 (40, Mandiant, 2026). Speed still matters. The difficulty is that speed measured as an average of closed tickets is a different quantity from speed at which intrusions are caught.
Four measures dominate SOC dashboards, and each rewards a behaviour that AI makes cheaper.
| Measure | What it rewards | How it is gamed, with or without AI | What it hides |
|---|---|---|---|
| Mean time to detect | A short interval between event and alert | Count only incidents found by alert; leave out those found late by a hunt or a third party; lower the threshold for what counts as an alert | The intrusions that were never detected, which have no start or end time to average |
| Mean time to respond | A short interval between alert and closure | Close the alert early and open a new ticket for the work; let an agent close low-risk classes in seconds | Whether the closure was right |
| Closure rate | Many alerts closed per analyst or per shift | Close by class without review; split one alert into several; raise the share of automated closures | Escape: the share of closures that should not have happened |
| Alert volume | A large number of alerts handled | Add noisy detections; count enrichment as handling | Cost: attention spent on alerts that never became cases |
An AI system that closes defined classes of alert (Chapter 7) improves mean time to respond and closure rate the day it is switched on, whether or not it closes correctly. An AI system that drafts detections (Chapter 6) raises the number of rules and, unless the alert budget holds, the volume. A manager who sets a target on any of these four numbers therefore buys the behaviour the number rewards, at machine speed. That is this book's own conclusion, drawn from how each number is computed, and not a finding of a source. The qualitative research on SOCs concerns the human side of the same pressure: a study of SOC analysts' perspectives on security alarms, whose title reports a 99 per cent false-positive experience (69, Alahmadi et al., 2022), and a survey of the research on alert fatigue (72, Tariq et al., 2025). Neither shows that a particular metric causes bad outcomes, and this chapter does not claim it.
The book's own conclusion is that a measure is safe to use as a target only if the behaviour that improves it is the behaviour the organisation wants. For closure rate, that holds only if every closure is correct, and that is exactly the property the measure does not observe. The remedy is not to abandon speed. It is to measure speed on the right population, to measure what speed cannot buy beside it, and to attach to every measure a check that detects the shortcut.
Four families and one rule
The proposed measures fall into four families, shown in Figure 20.1: speed, how fast verified incidents are contained; coverage, which techniques and assets the defence can be shown to see; quality of judgement, whether the conclusions of people and AI systems are right, where closure rate says nothing; and learning, whether the team is getting better. One rule runs through all four: no measure is reported without its gaming check, the control that would show the number moving for the wrong reason.
Speed
Speed is measured on verified incidents, not on alerts. An alert that is closed as benign does not enter the denominator, and an incident found by a hunt, a purple exercise or a third party does. This single change removes most of the gaming of MTTD, because the late and external discoveries that the old measure left out are now the cases that count.
Three intervals are worth recording for every verified incident, taken from the clocks the case record already holds (Chapters 7 and 10): time to flag, from the first event to the first flag by a person or a system (first_flag_at); time to confirmation, from the first flag to the point at which a person confirmed the incident (human_confirmed_at); and time to contain, from the first flag to the first effective containment action (action_at), so that a Level 3 action that runs before any person has confirmed the incident counts, as A1 did in INC-HM-2027-0455, 53 seconds after the flag. The three are reported by incident class, with the median and the 90th percentile, because an average hides the long tail that matters. They are never merged into one number. The two timestamps are also the moments from which the reporting clocks of NIS 2 Article 23 and DORA Articles 17 to 19 may start (3, European Union, 2022) (2, European Union, 2022), so the same record answers the board and the supervisor. Which moment counts as awareness is for counsel and not for this measure (Chapter 19).
For containment three further measures matter, the first two supplied by the records of Chapters 10 and 11 and defined here. The first is containment held: of the incidents in which containment was taken, the share contained without a reversal. A containment that has to be reversed because it hit a legitimate process is faster than no containment and worse than a correct one. The second is the stop-path time: the seconds from invoking the stop to the point at which the agent's credentials are dead, against the target in the mandate manifest. At Hansa Mutual the target for the investigation agent is 120 seconds, the live stop in INC-HM-2027-0455 took 57 seconds, and the drill that followed took 3 minutes 40 seconds and became finding FND-HM-0455-3. A speed figure that omitted the drill would have reported a healthy stop path. The third measure is the count of stops by class, with the share flagged precautionary and the share later reversed: a team that records no stops in a year has shown nothing about its agents, and a falling precautionary share may mean that holding the right feels expensive (Chapter 18).
The gaming check for speed is the reopen and reversal share: if the median time to contain falls while reversals or reopened incidents rise, the speed was bought. A second check is the share of verified incidents first found by the organisation itself, as against by a hunt or a third party, because a fall in time to flag that comes with a fall in internal detection means the denominator has changed.
Coverage
Coverage is measured as a map, not as a count. AI Threat, Chapter 30, classifies a control as verified, declared or failed, treats a control as a defence only when a test that re-runs its scenario has passed recently, and requires the control-to-threat coverage matrix to record shared dependencies, so that two controls that fail together are not counted as two (65, Nordqvist, 2026). Chapter 6 applies the classification to detections: a cell of the map is an ATT&CK technique (9, MITRE, n.d.) in an asset class, seen through a named data source, and it is verified when a recent test has fired the detection on replayed telemetry, declared when a detection exists with no recent passing test, and failed when the test failed or the data source stopped delivering.
Two measures follow. Verified coverage of priority techniques is the share of cells that matter to the organisation which are verified, with the declared and failed shares beside it. The priority set is the output of B1 Anticipate: intelligence selects the techniques and the critical assets, the map shows which are covered, and the difference is the quarter's work. Coverage by critical asset repeats the figure for the assets whose loss would stop a service, because a technique that is covered everywhere except on the claims-settlement platform is not covered. The hunts of Chapter 9 add a second source: each hunt ends in a coverage statement of what was searched and what was not, and the accumulated statements show which techniques were last hunted, where and how long ago.
The gaming check for coverage is the date of the last passing test, carried in every cell. Coverage can be inflated by declaring detections and never testing them, by mapping one rule to many techniques, and by dropping hard techniques from the priority set. A report that shows the declared share, the age of the oldest passing test and the number of cells dropped from the priority set during the quarter closes all three. Where the contract with a managed provider grants no evidence about the provider's detections, those cells stay declared or failed however good the provider's marketing; Chapter 16 treats the contract terms that change this.
Quality of judgement
Quality of judgement is the family that speed cannot buy, and it is the book's answer to what shows the quality of a team's judgement. Five measures belong to it.
- Escape rate by class is the share of closed alerts in a class that a later review shows should not have been closed. It is estimated from the sample and reported with its sample size, since Chapter 7 shows that 600 sampled closures with no escape support only an upper bound of roughly 0.5 per cent for the class.
- Seeded-incident catch rate is the share of injected known-malicious cases that the path catches, whether by the agent escalating them, by the sample reopening them or by the analyst. It measures the dangerous tail that sampling cannot see, but only for what the team chose to seed.
- Retrospective audit traces an intrusion found by other means back through the alert stream: did any alert point at it, and was it closed? Each trace is a finding for the class and the most informative evidence about escape the team will get. These three form the escape view.
- Oversight quality uses the metrics of Chapter 14: time to approval, rejection rate, reversals, caught-seed rate, reproduction rate and unassisted share. AI Red Team, Chapters 6 and 15, define approval quality by the first three and require that they are agreed with works councils first and reported in aggregate (64, Nordqvist, 2026). Hansa Mutual's report
OQM-HM-SOC-01for 2027-Q3 is the model: 9,600 proposals reviewed at 3.0 times the 2026 baseline, a median time to approval of 4.2 minutes, a rejection rate of 0.12, 24 of 28 seeded errors caught (0.86 against a threshold of 0.80) and a reproduction rate of 0.71 for tier T2, which missed its target of 0.80 and is flagged in the report. These figures are quoted unchanged from Chapter 14. No one metric stands alone, and a median that falls steeply while volume rises is the first sign of approval without review. - Cost per verified case prices judgement. It is the cost of the SOC's analyst time, platform and agent budget divided by the number of cases verified as incidents, and it replaces cost per alert. It rises when noisy detections consume attention and falls when the alert budgets of Chapter 6 hold. It can be gamed by under-staffing or by verifying fewer cases, so it is always read next to the escape view. The agent's monthly budget in the mandate manifest (EUR 9,000 for
HM-SEC-001) is the AI part of the numerator.
The gaming check for judgement is the seed itself: seeding is done by a person other than the reviewer, the register of seeds is kept from the analysts, and a seed missed at high severity freezes any extension of delegation for the class (Chapter 14). A catch rate computed from seeds the reviewers can recognise measures their memory.
Practical guide: Replacing a closure-rate target with three measures and a gaming check
Purpose. Replace a target on alerts closed per shift, or on mean time to close, with measures that do not reward closing wrongly.
Roles. The SOC lead owns the change. The detection engineering lead supplies the denominators. The employee representatives agree what is collected and how it is reported. The CISO signs the new report. The internal auditor, or the privacy officer where personal data is involved, checks the gaming checks.
- Withdraw the target, keep the figure. Stop setting a goal on closure rate or alerts handled. Keep the figure on the operational dashboard for capacity planning, labelled as such.
- Agree the scope first. Before any new figure is collected, agree with the employee representatives which measures are collected, at which level they are reported (team and class, never a named person) and for how long they are kept. Record the agreement in the works agreement or its annex (see the section on measures about people).
- Choose three measures. Take one from speed (time to contain for verified incidents, by class), one from quality of judgement (escape rate by class with the seeded-incident catch rate beside it) and one from learning (time from finding to verified control). Define each in the register by its numerator, denominator and source record.
- Attach one gaming check to each. Reversal share for time to contain, the seed protocol and a threshold for the escape view, and a passing re-test as the closing condition for the learning measure.
- Run in shadow for one quarter. Report the old and the new figures side by side to the SOC lead and the representatives only. Look for places where they diverge: a class with a fast closure time and a low catch rate is the finding the exercise exists to produce.
- Set thresholds, not targets. Where a number must trigger action, express it as a stop rule (catch rate below 0.80 freezes delegation) and not as a goal to be maximised.
- Review at 12 months. Check each measure for the shortcut it invites, and retire any that no longer distinguishes good from bad.
Definition of done. The closure-rate target is withdrawn, three measures with gaming checks are reported for one full quarter in the same form to the SOC lead and the representatives, and no figure in the report is computed per named person. Adapt the thresholds to the contract, the works agreement and the organisation's risk appetite.
Learning
Learning is the family that measures whether the team is getting better, and it is the least gameable by speed. Chapter 11 introduced the measures; this chapter places them beside the others.
Time from finding to verified control, reported as a median and a 90th percentile, is the interval from the opening of a finding to the passing of its re-test. Because the rule of AI Red Team is that a finding closes when the re-test passes and not when the change is merged, the figure cannot be improved by closing on a statement (64, Nordqvist, 2026). The three findings of PIR-HM-0455 took 21, 26 and 28 days from the review of 2027-05-06 to their passing re-tests, and the stop-path finding was the slowest. Recurrence rate is the share of findings in a class that return within 12 months, and it shows whether fixes held. Share of controls verified, declared and failed is the coverage measure of the previous section, seen as a trend. Age of the oldest open finding, reported by severity band, shows whether the backlog is managed or only the easy items are cleared.
Recoverability completes the family. AI Red Team argued that recoverability becomes a measured, continuously rehearsed property and belongs beside patch velocity in management reporting (64, Nordqvist, 2026), and NIST treats recovery as a planned and rehearsed activity with its own criteria (20, Bartock et al., 2016). For the blue team the measure is the share of critical services whose last recovery rehearsal met its stated recovery time. It belongs to B4 Respond, it is owned jointly by the incident commander and the IT operations owner, and it keeps the page honest about the point where containment ends and restoration begins.
The gaming checks are those of Chapter 11: closure requires a passing re-test, severity is set at opening, classes are fixed in the register schema and a repeat is linked, not reclassified as new. Security chaos engineering supplies the strongest check of all, because a chaos experiment that injects a condition and tests a steady-state hypothesis produces evidence that does not depend on the alert stream (58, Rinehart & Shortridge, 2023).
The board page
The board needs a view it can decide from, not a dashboard. AI Threat, Chapter 32, set the rule for the threat register: it reaches the board as one page with at most three decisions (65, Nordqvist, 2026). The blue team page follows the same rule, and for the same reason: a page that asks for no decision informs but does not govern, and a page that asks for ten decisions is not read.
The page has five parts. A header gives the period, the owner and the sources. Speed carries the time to contain for verified incidents, containment held, the count of stops and the stop-path result, live and in drill. Coverage carries the verified, declared and failed shares for the priority techniques and the age of the oldest passing test. Judgement carries the escape view, with the escape rate by class, and the oversight-quality figures, each with its count. Learning carries the time from finding to verified control, recurrence and recoverability. A short decisions block closes the page with at most three requests, each tied to a measure that justifies it: to hold or extend a delegation, to accept a named gap until a date, or to fund a specific piece of work. A decision that cannot be traced to a measure does not belong on the page.
Three habits keep the page truthful. Every figure is shown with its count, because 0.86 from 28 seeds and 0.86 from 280 seeds are different statements. Every figure is produced by a pipeline from the records, not typed into the page, so that a reader can follow it back to the case, the detection and the test. And the page is read together with the register, which a supervisor can inspect. DORA Article 5 and NIS 2 Article 20 place responsibility for ICT and cybersecurity risk management with the management body (2, European Union, 2022) (3, European Union, 2022); the architectural implication is that the page is the evidence that the body was given what it needs to exercise that responsibility, and that its decisions are recorded.
Worked example: reporting/blue-team-page.yaml
The following file is illustrative. It is the page that Hansa Mutual's group CISO sends to the executive board for the third quarter of 2027. The oversight figures are those of OQM-HM-SOC-01 in Chapter 14. The stop-path entry carries the last measured results, taken in the second quarter, and is labelled so; the incident, containment and reversal counts are year to date to the end of Q3, so that the reversal of April belongs to them.
# reporting/blue-team-page.yaml  (illustrative)
page: BTP-HM-2027-Q3
period: 2027-Q3
owner: group-ciso
reporting_level: team          # never by person
agreed_with: [konzernbetriebsrat, polish-service-centre-representatives]
sources: [OQM-HM-SOC-01, case-register, coverage-map, finding-register, drill-register]
speed:
  counts_period: year-to-date-to-end-of-q3   # includes the April reversal
  time_to_contain_minutes: {median: 6, p90: 21, incidents: 12}   # from first flag
  containment_held: {incidents_with_containment: 12, held: 11, reversed: 1}
  stops: {invoked: 3, precautionary: 2}
  stop_path_seconds:           # last measured, second quarter
    live_2027_04_12: 57
    drill_2027_04_27: 220
    retest_2027_06_03: 106
    target: 120
  gaming_check: reversal_share
coverage:
  priority_techniques: 34
  verified: 25
  declared: 7
  failed: 2
  oldest_passing_test_days: 74
  gaming_check: date_of_last_passing_test
judgement:
  escape_rate_by_class:
    SC-01: {sampled: 640, escapes: 1, rate: 0.002}
    SC-02: {sampled: 520, escapes: 0, upper_bound: 0.006}
  seeds: {injected: 28, caught: 24, caught_seed_rate: 0.86, threshold: 0.80}
  oversight: {proposals: 9600, median_minutes: 4.2, rejection_rate: 0.12,
              reproduction_rate_t2: 0.71, reproduction_target: 0.80, flag: target_missed}
  gaming_check: seeds_set_by_other_than_reviewer
learning:
  finding_to_control_days: {median: 19, p90: 41, findings_closed: 23}
  recurrence_12_months: 0.04
  recoverability: {services_drilled: 6, within_objective: 5}
  gaming_check: closure_requires_passing_retest
decisions_requested:
  - id: req-1
    measure: judgement.oversight.reproduction_rate_t2
    request: hold class SC-03 at Level 2 Supervised through 2027-Q4
  - id: req-2
    measure: coverage.failed
    request: accept two failed cells (T1098, T1567) until 2027-12-15 or fund the work
decision_record: AIDR-0778
The page has two requests, which is within the limit. It shows the time to contain and the escape rate with their counts, and it reports one reversed containment in twelve, year to date to the end of Q3. The stop-path entry gives both the 57 seconds on the day and the 3 minutes 40 seconds of the drill, with the re-test of 1 minute 46 seconds, because a page that gave only the live figure would report a healthy stop path. The reproduction rate is shown as a missed target and drives the first request.
Benchmarks and their limits
Boards ask for a comparison, and comparison is possible only within limits. Mandiant's M-Trends reports dwell time and the share of internal detection from its own incident-response engagements (40, Mandiant, 2026); that population is organisations that called for help, so the figures are a reference for direction, not a target. The SANS SOC survey is a practitioner survey and is not peer reviewed (74, Crowley, 2025); it shows what other SOCs say they do. The measures proposed in this chapter have no published benchmark, since they are the book's own.
Three rules limit the use of benchmarks. Compare like with like: a median over verified incidents is not comparable with a mean over alerts. Compare a trend with the organisation's own earlier figure before comparing it with another organisation's. And never set a target at the benchmark, since a target set at a peer's number invites the shortcuts that the gaming checks exist to find. The organisation's own history, with the counts and the dates of changes to delegation, mandates and detections, is the most useful comparison it will have.
Measures about people
SOC tooling records every query, ticket and approval, and the same logs that give the team its measures can give a manager a ranking of analysts overnight. AI Boss treats this as a question of algorithmic management and of co-determination (67, Nordqvist, 2026); this chapter states the rule that keeps the blue team's measures on the right side of it. Measures are about the system, the class and the team. They are agreed with employee representatives before they are collected. They are reported in aggregate. And the exact terms are written down.
At Hansa Mutual the Konzernbetriebsrat co-determines under BetrVG §87(1) no. 6 on tools that can monitor employees' behaviour or performance, and the SOC annex to the group works agreement KBV-IT-2024 covers the oversight metrics and the seeding programme; the Polish service centre's representatives agreed the same terms and the Swedish subsidiary consults its unions. At Nordvik Region the union has negotiated that closure rates and similar measures are never reported by name. Data about identified employees is personal data under the GDPR, which leaves Member States room for specific rules on employment data in Article 88 (8, European Union, 2016), so the data protection officer checks purpose, retention and access. These are organisational implications and not legal advice; the position differs by Member State and by agreement.
Four limits follow from the rule.
- No individual scoring. No measure in this chapter is computed per named analyst, and none enters a performance review. Where a pattern appears to attach to a person, the response is to examine the class, the tier, the volume and the tooling, as Chapter 14 does with its time floor.
- A minimum group size. A figure for a group so small that it identifies a person is an individual figure. Nordvik's unit has six analysts, so its measures are reported for the unit as a whole and never by shift, by week or by reviewer; as a default, no figure is shown for a group of fewer than five people, the floor agreed at Hansa Mutual, and the representatives may set a higher one.
- Agreement before collection. The agreement precedes the data. A measure that was collected for another purpose, such as a ticket field, does not become a measure of performance because it is available.
- Seeds are not traps for individuals. Analysts are told that seeding exists; the results are reported for the team; a missed seed is analysed as a finding on the protocol.
The experience of being measured is a subject of its own, and Chapter 21 treats it. The conclusion of this chapter is design-oriented: a measure of the system's judgement is useful because the people whose work it describes have fewer reasons to game it, and that property holds only while the rule above holds.
Across the degrees of delegation
AI can help to compute and present measures, and the limit is that it must not move the denominators or set the targets. The mode describes how the AI is deployed and whose identity it uses; the level describes who decides each action. None of the actions here decides about a named person's access to work.
| Activity | Usual mode | Default ceiling | Condition |
|---|---|---|---|
| Draft the commentary for the board page from the metrics | Mode 1 Conversational assistants or Mode 2 Embedded workplace assistants | Level 1 Assisted | Figures supplied by the pipeline; a named person checks every statement against the record and sends |
| Compute the measures from the case, detection and finding records | Mode 5 Autonomous production agents | Level 3 Bounded | Read-only; definitions in version control; the denominator rules cannot be edited by the agent |
| Flag a measure that moves against its gaming check | Mode 4 Built AI applications or Mode 5 | Level 3 Bounded | Raises a finding; takes no action on delegation |
| Propose a change to a threshold or a definition | Mode 3 Agentic work tools | Level 2 Supervised | A pull request approved by the SOC lead and, where it touches people, the representatives |
| Set a target, a threshold or a decision request | Not delegated | Level 0 Advisory | The CISO and the board hold these |
Nordvik Region and Hansa Mutual
Nordvik Region. The Region's board receives a quarterly page that the CISO signs. Its measures are those the Region can compute from records it holds: verified coverage of the few rules it owns, the seeded-error catch of the weekly deep-review summaries (7 of 9 seeded errors caught in the first quarter, a count for the team of six and, with nine seeds, too few to read as more than a signal), the reopened closures from the weekly sample of the provider's out-of-hours closures (AIDR-0712) and the age of open findings. The provider's own measures enter the page only after the Region has obtained the data in annex MS-2 (Chapter 16), because a figure the Region cannot trace to a record it holds is declared, not verified. Because the unit has six analysts, every figure is reported for the unit as a whole, and the seed count is never broken down by reviewer. The decision record AIDR-0723 adopts the page, withdraws the practice of reporting closed alerts as an achievement, and agrees the reporting level with the union.
Hansa Mutual. The group's page, shown above, reports a median time to contain of 6 minutes, a caught-seed rate of 0.86, containment held in 11 of 12 incidents and a median of 19 days from finding to verified control, and it asks for two decisions. Hansa's problem is not too little data but too much, and the page therefore selects. The decision record AIDR-0778 replaces the closure-rate figure on the executive board's page with the three-measure set of the practical guide, keeps closure rate on the operational dashboard for capacity planning only, and fixes the reporting level at team and class, as agreed with the Konzernbetriebsrat and the Polish representatives. The two organisations differ in what they can measure and not in what they should: Nordvik cannot yet see its provider, and Hansa can see most of its own estate, which makes the discipline of agreed, aggregate reporting the harder to keep.
Outlook
The pressure of alert volume on analysts is documented in the SOC literature cited above. It is observable that organisations report MTTD, MTTR and closure rate to boards and that AI closure of alert classes improves the last two on the day it is switched on. It is observable that regulators of the financial sector and of essential and important entities require incident management and reporting that the case record can support. It is expected, because NIS 2 Article 20 and DORA Article 5 place oversight of cybersecurity and ICT risk with the management body, that boards will ask what an organisation can show about the quality of its automated decisions and not only their speed (3, European Union, 2022) (2, European Union, 2022). Whether a common set of judgement measures emerges across organisations is speculation; no present evidence shows it, and the measures proposed here are the book's own and not benchmarked.
Summary
Time to detect, time to respond, closure rate and alert volume reward closing alerts faster, and AI makes closing faster the cheapest thing a SOC can do. This chapter proposed four families of measure instead. Speed is measured on verified incidents by class, with containment held, the count of stops and the stop-path time, live and in drill, beside it. Coverage is a map of verified, declared and failed cells with the date of the last passing test. Quality of judgement combines escape rate, seeded-incident catch rate, retrospective audit, oversight quality and cost per verified case. Learning is the time from finding to verified control, recurrence and recoverability. Every measure carries a gaming check, and a measure reported without one is a target waiting to happen. These measures concern B1 Anticipate through the priority set, B2 Detect through verified detections and alert cost, B3 Investigate through escape and oversight quality, B4 Respond through containment and recoverability, and B5 Learn through the finding-to-control path.
The board sees one page with at most three decisions, each traced to a measure, and every figure is shown with its count and produced from the records. Benchmarks are used for direction, never as targets. Measures about people are agreed with employee representatives before collection, reported in aggregate, never computed per named analyst and never shown for groups small enough to identify a person.
At Nordvik Region the page is built from the records the Region holds and includes the provider's measures only once annex MS-2 delivers the data; at Hansa Mutual it reports a median time to contain, a caught-seed rate of 0.86, containment held in 11 of 12 incidents and a median of 19 days from finding to verified control. The reader can begin with one change: pick the measure your team is rewarded for, write down the shortcut that would improve it without improving the defence, and add the check that would show the shortcut. Chapter 21 turns from the measures to the person who is measured, the analyst at work, and to what the transformed team feels like from the inside.
Sources
- Nordqvist, G. (2025). Architecture as Code. The Architecture as Code Series, Book 1. (61, Nordqvist, 2025)
- Nordqvist, G. (2026). AI Red Team: AI as an Active Part of Cyber Defence in European Enterprises and Public Authorities. The Architecture as Code Series, Book 4. (64, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Threat: Are the Dystopias Coming True? Evidence, Risk and Response for European Enterprises and Public Authorities. The Architecture as Code Series, Book 5. (65, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Boss: When Artificial Intelligence Manages People in European Enterprises and Public Authorities. The Architecture as Code Series, Book 7. (67, Nordqvist, 2026)
- European Parliament and Council of the European Union (2022). Regulation (EU) 2022/2554 on digital operational resilience for the financial sector (DORA). Official Journal of the European Union. (2, European Union, 2022)
- European Parliament and Council of the European Union (2022). Directive (EU) 2022/2555 on measures for a high common level of cybersecurity across the Union (NIS 2 Directive). Official Journal of the European Union. (3, European Union, 2022)
- European Parliament and Council of the European Union (2016). Regulation (EU) 2016/679 (General Data Protection Regulation). Official Journal of the European Union. (8, European Union, 2016)
- MITRE Corporation. MITRE ATT&CK: Adversarial Tactics, Techniques, and Common Knowledge. (9, MITRE, n.d.)
- Bartock, M. et al. (2016). Guide for Cybersecurity Event Recovery. NIST SP 800-184. (20, Bartock et al., 2016)
- Mandiant (2026). M-Trends 2026: Data, Insights, and Strategies From the Frontlines. Google Cloud Blog. (40, Mandiant, 2026)
- Rinehart, A. & Shortridge, K. (2023). Security Chaos Engineering: Developing Resilience and Safety at Speed and Scale. O'Reilly Media. (58, Rinehart & Shortridge, 2023)
- Alahmadi, B. A., Axon, L. & Martinovic, I. (2022). 99% False Positives: A Qualitative Study of SOC Analysts' Perspectives on Security Alarms. 31st USENIX Security Symposium. (69, Alahmadi et al., 2022)
- Tariq, S. et al. (2025). Alert Fatigue in Security Operations Centres: Research Challenges and Opportunities. ACM Computing Surveys 57(9). (72, Tariq et al., 2025)
- Crowley, C. (2025). SANS 2025 SOC Survey. SANS Institute. (74, Crowley, 2025)